Healthcare data extraction for medical records, forms, and claims
Turn healthcare documents into structured data healthcare teams can trust. Nutrient Data Extraction API extracts and validates information from forms, records, and scanned documents, giving teams traceable, production-ready data while directing human attention to exceptions — not every field. Encrypted transport and access controls help support the security requirements of HIPAA-sensitive workflows.
Trusted by enterprises, governments, and teams building document workflows at scale
Used by Lufthansa, Disney, Autodesk, UBS, Dropbox, IBM
Lufthansa
Disney
Autodesk
UBS
Dropbox
IBM
Lufthansa
Disney
Autodesk
UBS
Dropbox
IBM
USE CASES
Medical data extraction use cases
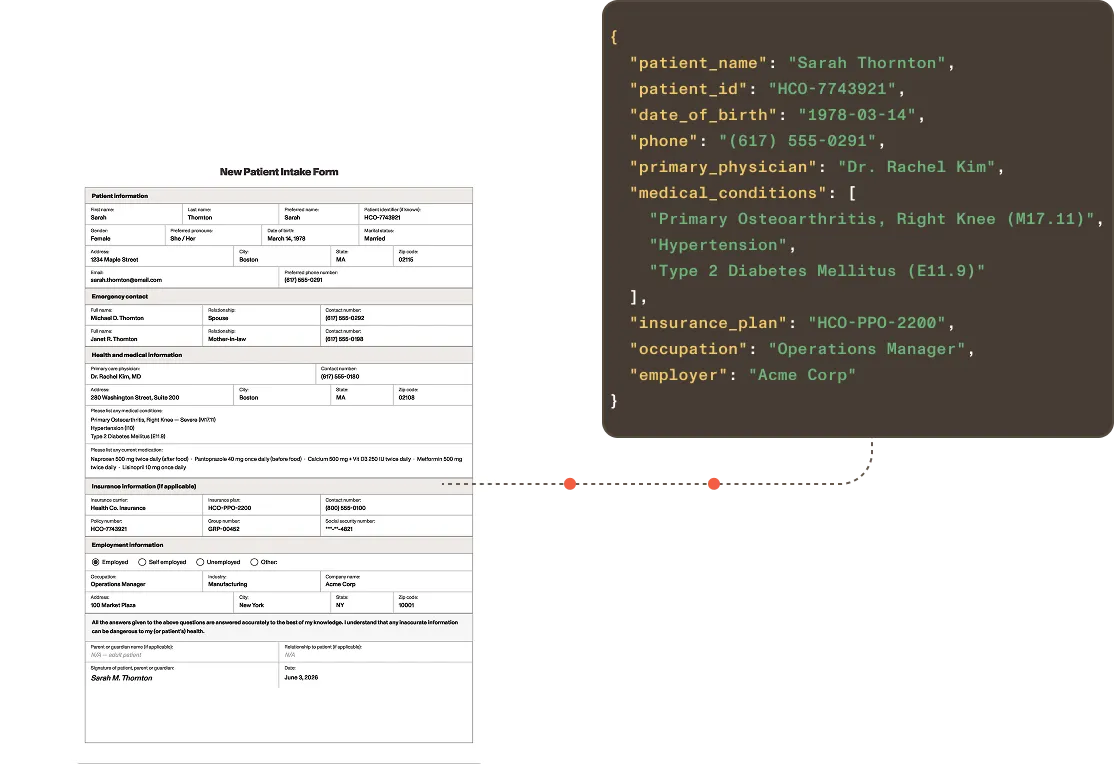
Patient intake
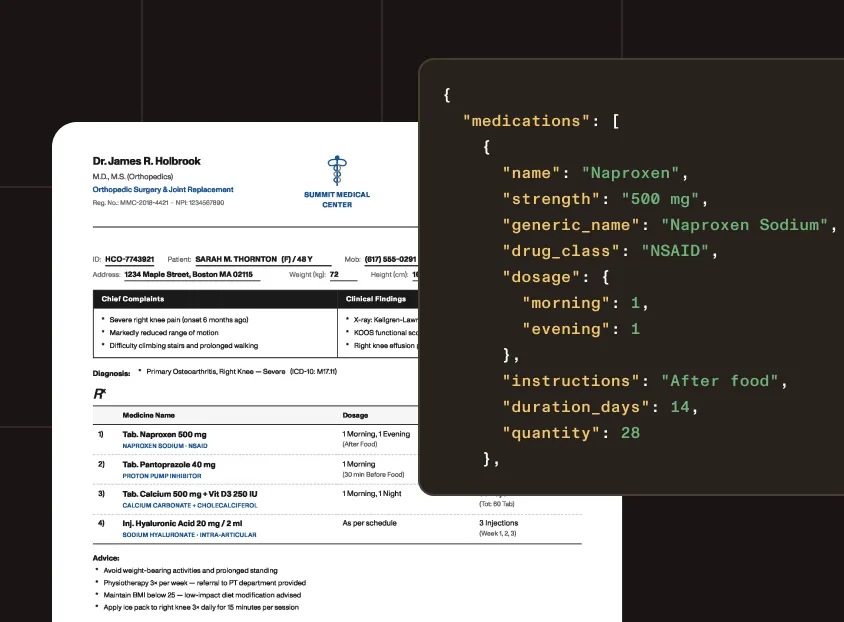
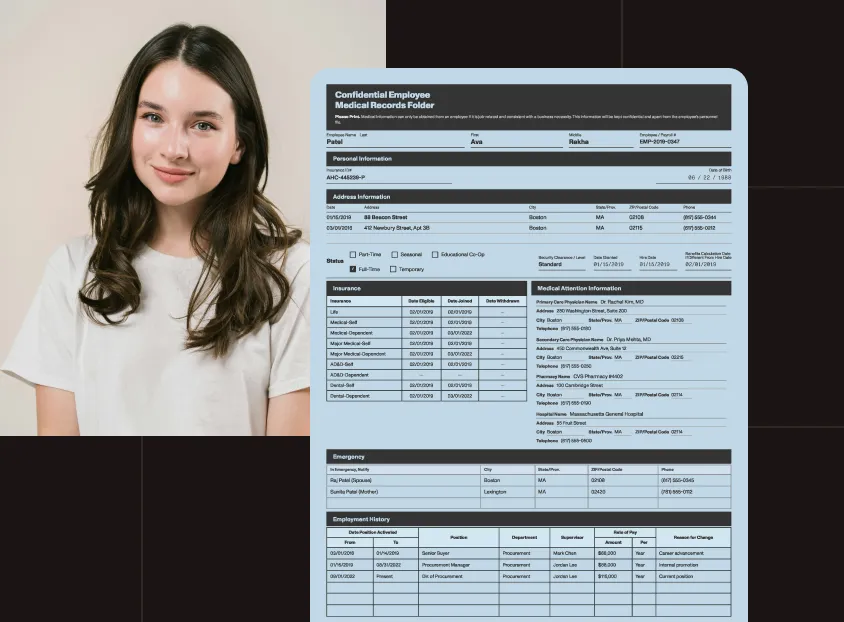
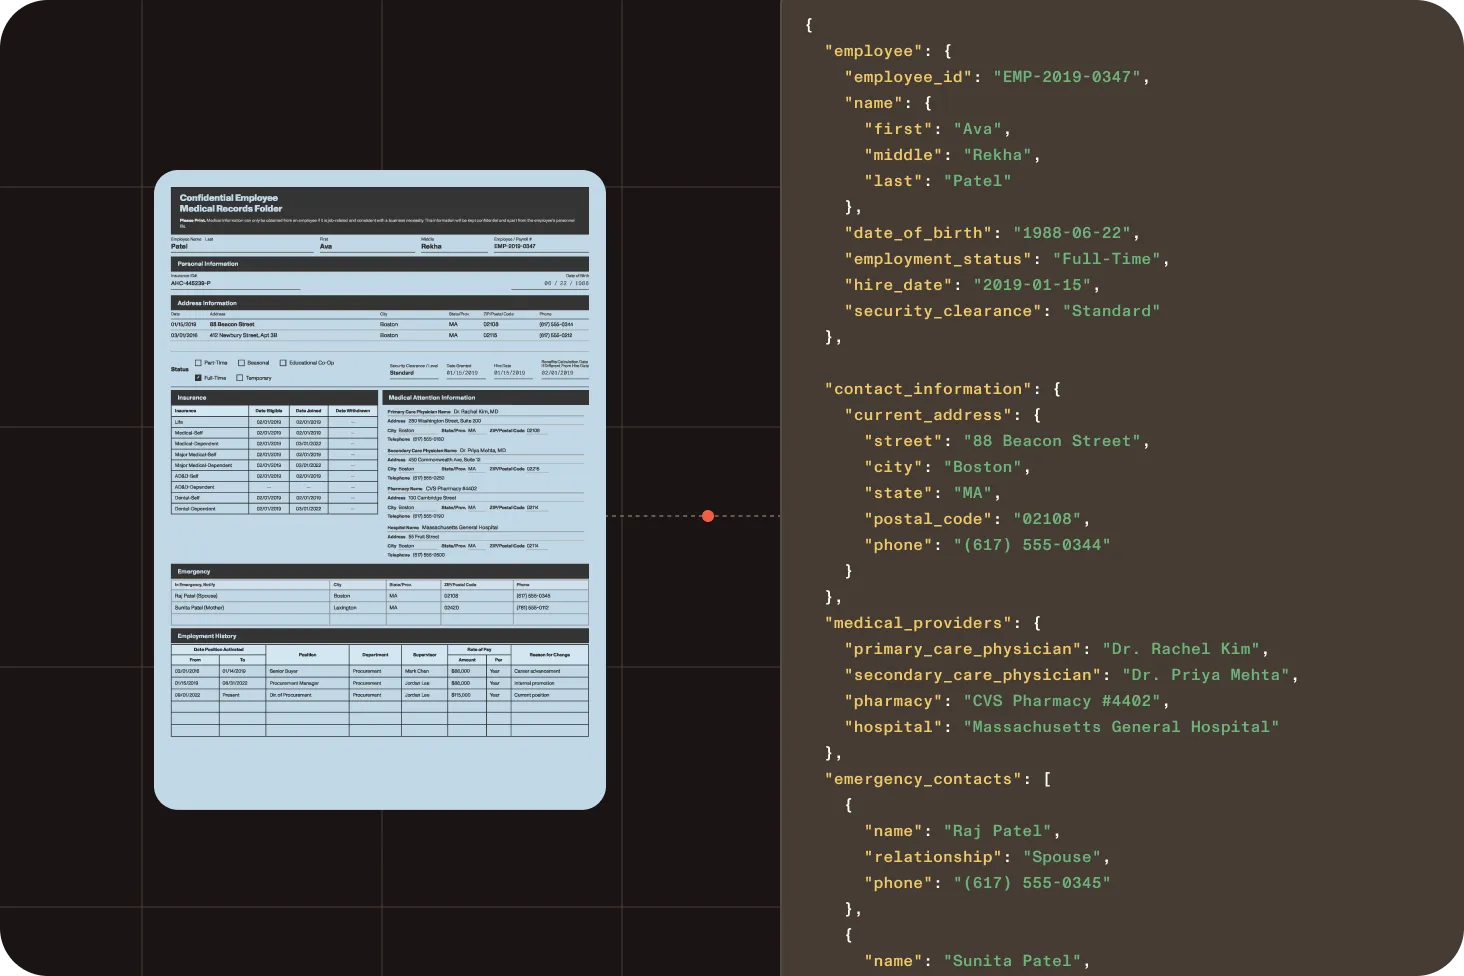
Extract patient demographics, insurance details, consent fields, checkboxes, signatures, and supporting information from intake documents.
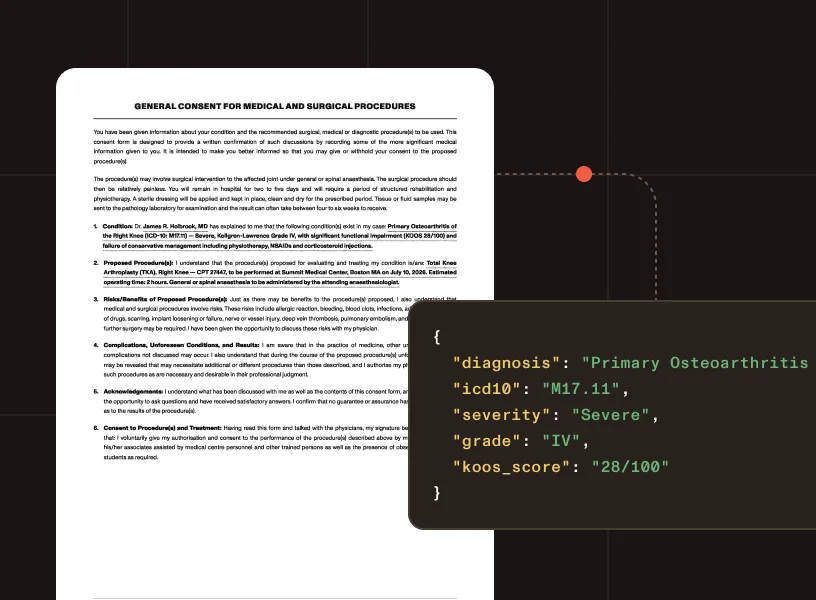
Prior authorization and referrals
Structure provider, payer, procedure, diagnosis, date, authorization, and supporting information for review and routing. See prior authorization automation for the full workflow.
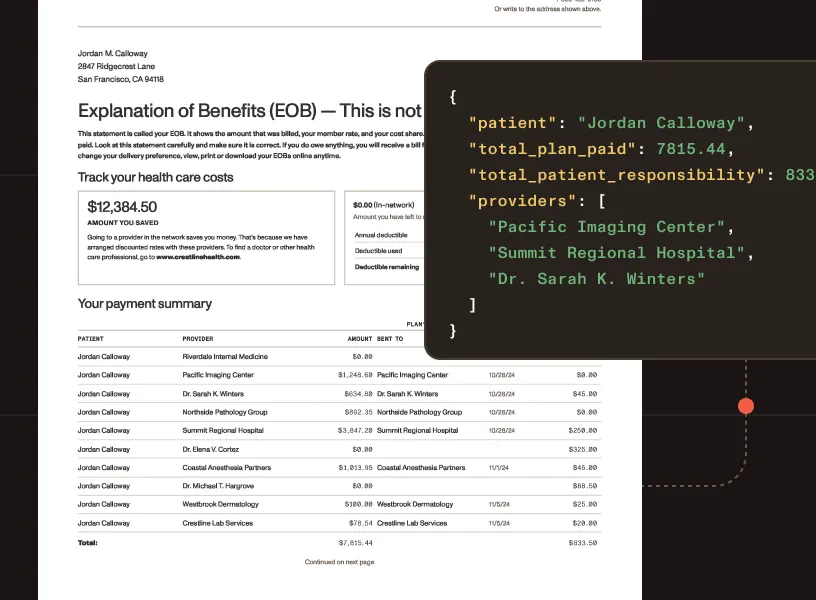
EOBs and claims documents
Automate extraction of payer details, dates, amounts, codes, patient responsibility, payment details, and structured tables from EOBs and claims documents. See a coding agent build an underpaid-claims checker.
Lab results and prescriptions
Extract test names, values, reference ranges, dates, prescription details, provider information, and structured fields from lab and prescription documents.
Medical records and packets
Prepare mixed scanned and digital medical records for review, search, AI, and downstream workflow use. See release of information automation for records-request workflows.
WALKTHROUGH
See it in action
0:00
0:00
GOVERNED EXTRACTION
Why not rely on LLM-only extraction for medical documents?
LLMs can reason over documents, but medical workflows need deterministic, auditable output grounded in the source file — not generated answers that vary between runs.
Predictable structured output
Typed output remains tied to the source document — not generated answers that change between runs.
Confidence signals for routing and review
Flag uncertain values before they move downstream into patient records or administrative systems.
Coordinates and page references
Every extracted value is anchored to its source location for traceability and human review.
Layout-aware structure
Lab tables, intake forms, checkboxes, and key-value regions preserved — not flattened into plain text.
Human review before downstream use
Support validation steps before structured data enters patient records, claims systems, or administrative workflows.
Auditability for compliance workflows
Source context and page detail support audit trails across charts, claims, and lab results.
WHAT YOU CAN EXTRACT
Extract data from medical records: Fields we capture
Patient and provider details
Names, DOBs, NPI numbers, addresses, and identifiers from intake and referral documents.
Diagnosis and procedure codes
ICD-10, CPT, and related codes extracted with confidence scores for validation before downstream use.
Payer and insurance information
Payer names, policy numbers, group IDs, and coverage details from insurance and claims documents.
Lab values and reference ranges
Test names, result values, units, and reference ranges preserved from lab reports.
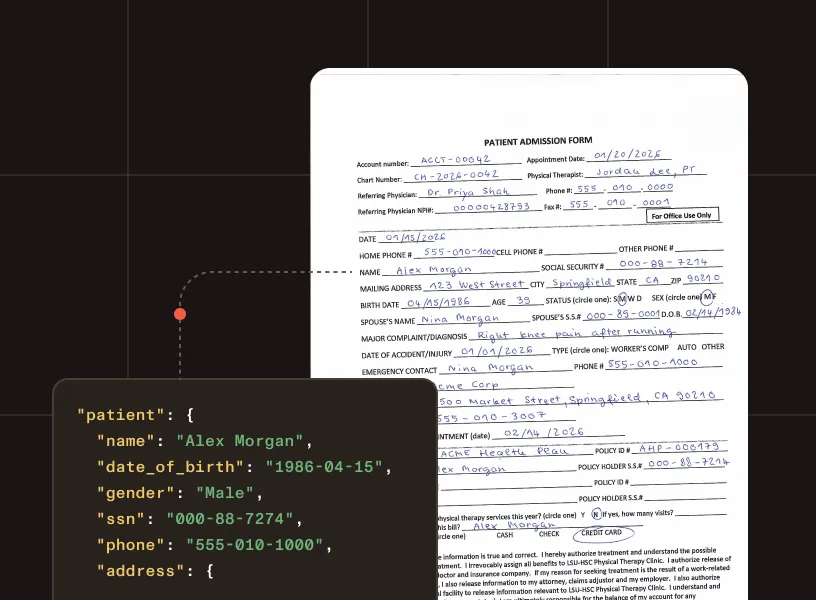
Form fields and handwritten values
Structured key-value regions, handwritten fields, and checkbox states captured with ICR — with confidence scores for review.
Tables and multirow structured data
Tables from EOBs, prior authorization forms, and claims documents, preserved with row and column context.
HOW IT WORKS
Healthcare document processing, step by step
Text
For fast extraction from born-digital records and forms with a reliable text layer.
PDF to Markdown RAG Search
Structure
For OCR-backed extraction from scanned records with simple layouts.
Scans Photos Tables
Understand
For forms, complex layouts, tables, printed handwriting, and richer document structure.
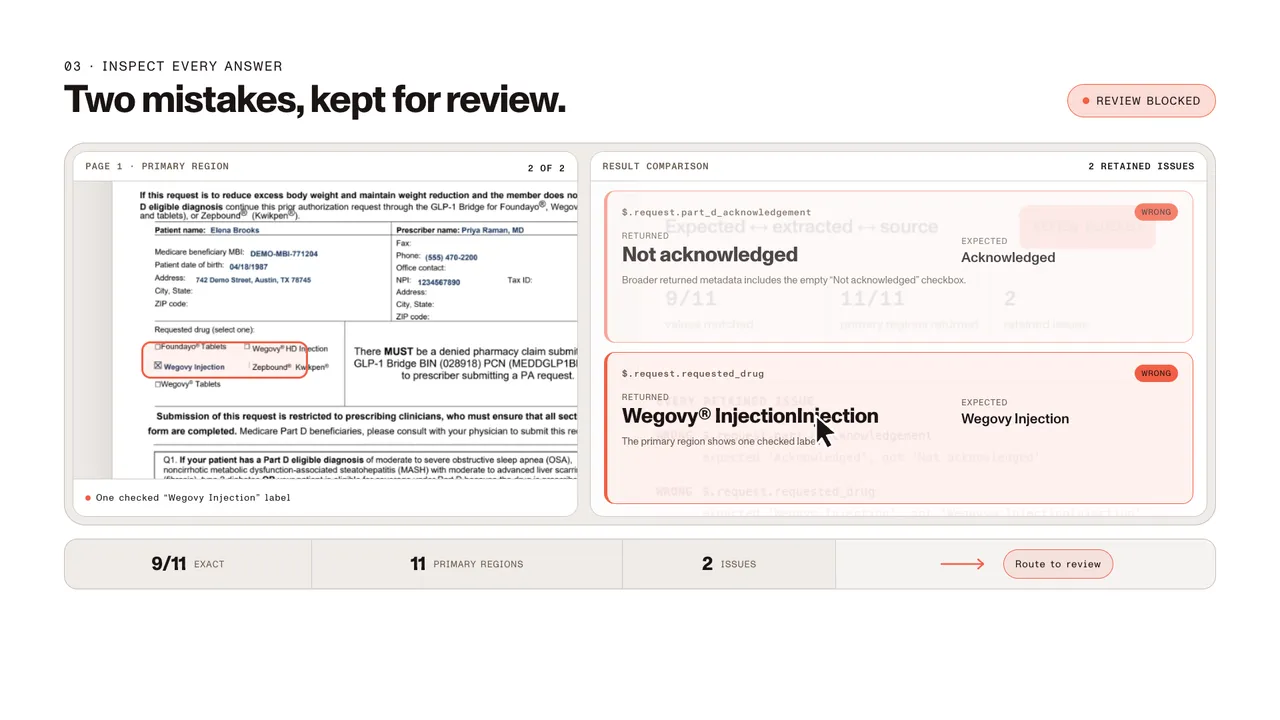
This is one reviewed run on a selected public form populated with privacy-safe demo values. It isn’t an accuracy, production, or performance benchmark.
0:00
0:00
Prior authorization intake
A selected public Centers for Medicare and Medicaid Services (CMS) prior authorization form populated with privacy-safe demo values and no protected health information (PHI).
200 real-world documents. Three metrics. Results published with
every release.
SOC 2 Type 2 audited
Backed by Nutrient’s SOC 2 Type 2 security practices and built for
use in business-critical and compliance-sensitive workflows.
Trust and compliance
HIPAA-aware healthcare OCR in production
TLS encryption by default
All API communication is TLS-encrypted. Documents in transit are
protected end to end.
HIPAA-compatible architecture
No document retention on paid plans, encrypted transport, and
access controls designed to support HIPAA-sensitive workflows.
Medical document extraction questions
Can the API handle handwritten medical forms?
Yes. For hand-completed fields, checkboxes, and handwritten values, the API applies intelligent character recognition (ICR) to capture what standard OCR misses. Every extracted value includes a confidence score so uncertain fields can be flagged for human review before moving downstream.
What file formats are supported?
Data Extraction API processes PDFs; images (including scans and photos); and Word, Excel, and PowerPoint files. It handles scanned PDFs, fillable forms, and mixed digital/image-based documents without requiring a separate OCR pipeline.
How do I validate extracted data before it enters downstream systems?
Every extracted element includes confidence scores, page references, and coordinates so you can compare outputs, flag low-confidence fields for human review, and trace values back to the source document before they move into patient records, claims systems, or administrative workflows.
Is this a full healthcare platform or an extraction API?
Nutrient Data Extraction API is an extraction layer — not an EHR, claims platform, or workflow management system. It extracts structured data from medical documents so that data can be reviewed, validated, and routed into the systems your team already uses. See the Data Extraction API overview for the full capability set, or the comparison hub for how it stacks up against other extraction platforms.
Can we extract data from patient records without sending them to a cloud API?
Yes, with the Data Extraction SDK. The Data Extraction API runs in Nutrient’s cloud, but the SDK runs the same engine in Python or Java on servers you control. Text and layout recognition run on those servers, and if you also host the optional AI model, patient records never leave your infrastructure. Talk to Sales about a self-hosted setup.
To try it on a set of sample records first, use Nutrient Extract Studio, a desktop app for Apple silicon Macs that runs the same engine. With an AI model running on that Mac, the records stay on the Mac. You sign in with a free Nutrient account, runs use Data Extraction credits, and Nutrient receives only page counts. Learn about Extract Studio for macOS.
How do I define the fields to extract from medical documents?
Use the schema generator in Studio — upload example forms, records, or claims documents and describe the document type. It then generates a JSON Schema you can use directly with /extract. You can also write the schema manually for fields like patient details, diagnosis codes, dates, and payer information. Refer to the documentation for supported field types and limits.
When should I use agentic mode for medical documents?
Use agentic mode for medical documents that require the deepest visual understanding — degraded scans, faxed records, low-quality images, handwriting, and documents with embedded images or diagrams where understand mode produces insufficient results. Agentic mode adds a vision language model (VLM) on top of the understand pipeline for complex visual content. It costs 18 credits per page.
GET STARTED
Start extracting data from medical documents
5,000 free credits per month — no credit card required.
Your free account includes:
5,000 Data Extraction API credits per month
Parse PDFs, scans, images, and Office files
Typed JSON output with confidence scores and source context