Extract text from PDFs in Python with pypdf and OCR

Table of contents
To extract text from a PDF in Python, open it with pypdf.PdfReader and call page.extract_text() for each page. This reads an existing text layer; it doesn’t recognize text in images. For scanned PDFs, run optical character recognition (OCR) first. This tutorial covers local extraction and a Nutrient API workflow with an explicit OCR step.
Skip the parsing stack: One API call
If your application needs to extract text from PDFs, including scans, Nutrient’s PDF OCR API returns it in one request, with a free tier and no credit card. Method 2 below shows the Python code; Method 1 covers pypdf.
What kind of PDF are you parsing?
The input determines which extraction method you need:
- Digitally generated PDF — Use pypdf(opens in a new tab) to read the existing text layer. Reading order and spacing can still need cleanup.
- Image-only scan — Run OCR to recognize the text. Calling
extract_text()alone won’t recover words from a page image. - Scan with an OCR layer —
pypdfcan read that layer, but recognition errors from the earlier OCR remain. - Password-protected PDF — Supply the authorized password before extraction. Encryption and OCR are separate concerns.
The examples cover local extraction with pypdf and OCR with Nutrient DWS Processor API. For new cloud extraction workflows, consider Nutrient Data Extraction API. Its Markdown extraction guide includes Python examples for the separate /extraction/parse endpoint. Review cloud-processing requirements before uploading confidential documents.
Requirements
Use Python 3.12 or newer and a virtual environment. Create a working folder for this tutorial:
mkdir text_extract_pdfcd text_extract_pdfpython3 -m venv .venvsource .venv/bin/activateOn Windows, create the environment with py -m venv .venv and activate it with .venv\Scripts\Activate.ps1 in PowerShell. Create app.py in the working folder.
Install pypdf(opens in a new tab) to read PDFs and extract their text:
python -m pip install pypdfUse these two test PDFs:
Save the PDFs beside app.py and update the file names in the examples to match.
Method 1: Extract text from PDF using pypdf
To extract text from a PDF in Python, open the file with PdfReader and call .extract_text() on each page. pypdf is a Python library for reading and manipulating PDF files. Here’s how to extract text from each page:
from pypdf import PdfReader
reader = PdfReader("compressed.tracemonkey-pldi-09.pdf")for page in reader.pages:    print(page.extract_text() or "")
Run python app.py to print the extracted text in your terminal. Check the result against the PDF: Columns, ligatures, and positioned text can affect order and spacing. The code creates a PdfReader(opens in a new tab) object. Then it loops over the pages with the .pages(opens in a new tab) property and prints each page’s text with the .extract_text(opens in a new tab) method.
Skipping headers and footers with pypdf
You can pass pypdf visitor functions, which it calls with each operator or text fragment. The text visitor receives five arguments: the text, the current transformation matrix, the text matrix, the font dictionary, and the font size. Combine the text and current transformation matrices with mult(tm, cm) to calculate the position in page user space.
The following example filters fragments from one page of this PDF document(opens in a new tab) using a y-coordinate range. It also keeps fragments at y == 0 to preserve line breaks in this file. These conditions are specific to the example. The pypdf extraction guide(opens in a new tab) warns that coordinates can be difficult to interpret in complex documents:
from pypdf import PdfReader, mult
reader = PdfReader("GeoBase_NHNC1_Data_Model_UML_EN.pdf")page = reader.pages[3]
parts = []
def visitor_body(text, cm, tm, font_dict, font_size):    y = mult(tm, cm)[5]    if 50 < y < 720 or y == 0:        parts.append(text)
page.extract_text(visitor_text=visitor_body)print("".join(parts))
How to extract text from encrypted PDFs in Python
pypdf can decrypt supported encrypted PDFs when you provide the correct password. The following example checks the decryption result before reading pages.
To work with encrypted documents, you’ll need to install the cryptography package:
python -m pip install cryptographyUse the .decrypt method to decrypt a PDF file before extracting text from it:
from pypdf import PdfReader
reader = PdfReader("encrypted-pdf.pdf")
if reader.is_encrypted:    if not reader.decrypt("password"):        raise ValueError("The PDF password is incorrect.")
# Extract text from all pages.for page in reader.pages:    print(page.extract_text() or "")
Method 2: Extract text with Nutrient and OCR
This example uses the Nutrient DWS Processor API /build workflow and a Processor API key. The request explicitly applies OCR in English and asks for plain text and structured text. Structured text describes text elements and their positions; it isn’t an application-specific invoice or table schema.
Step 1: Sign up and get your API key
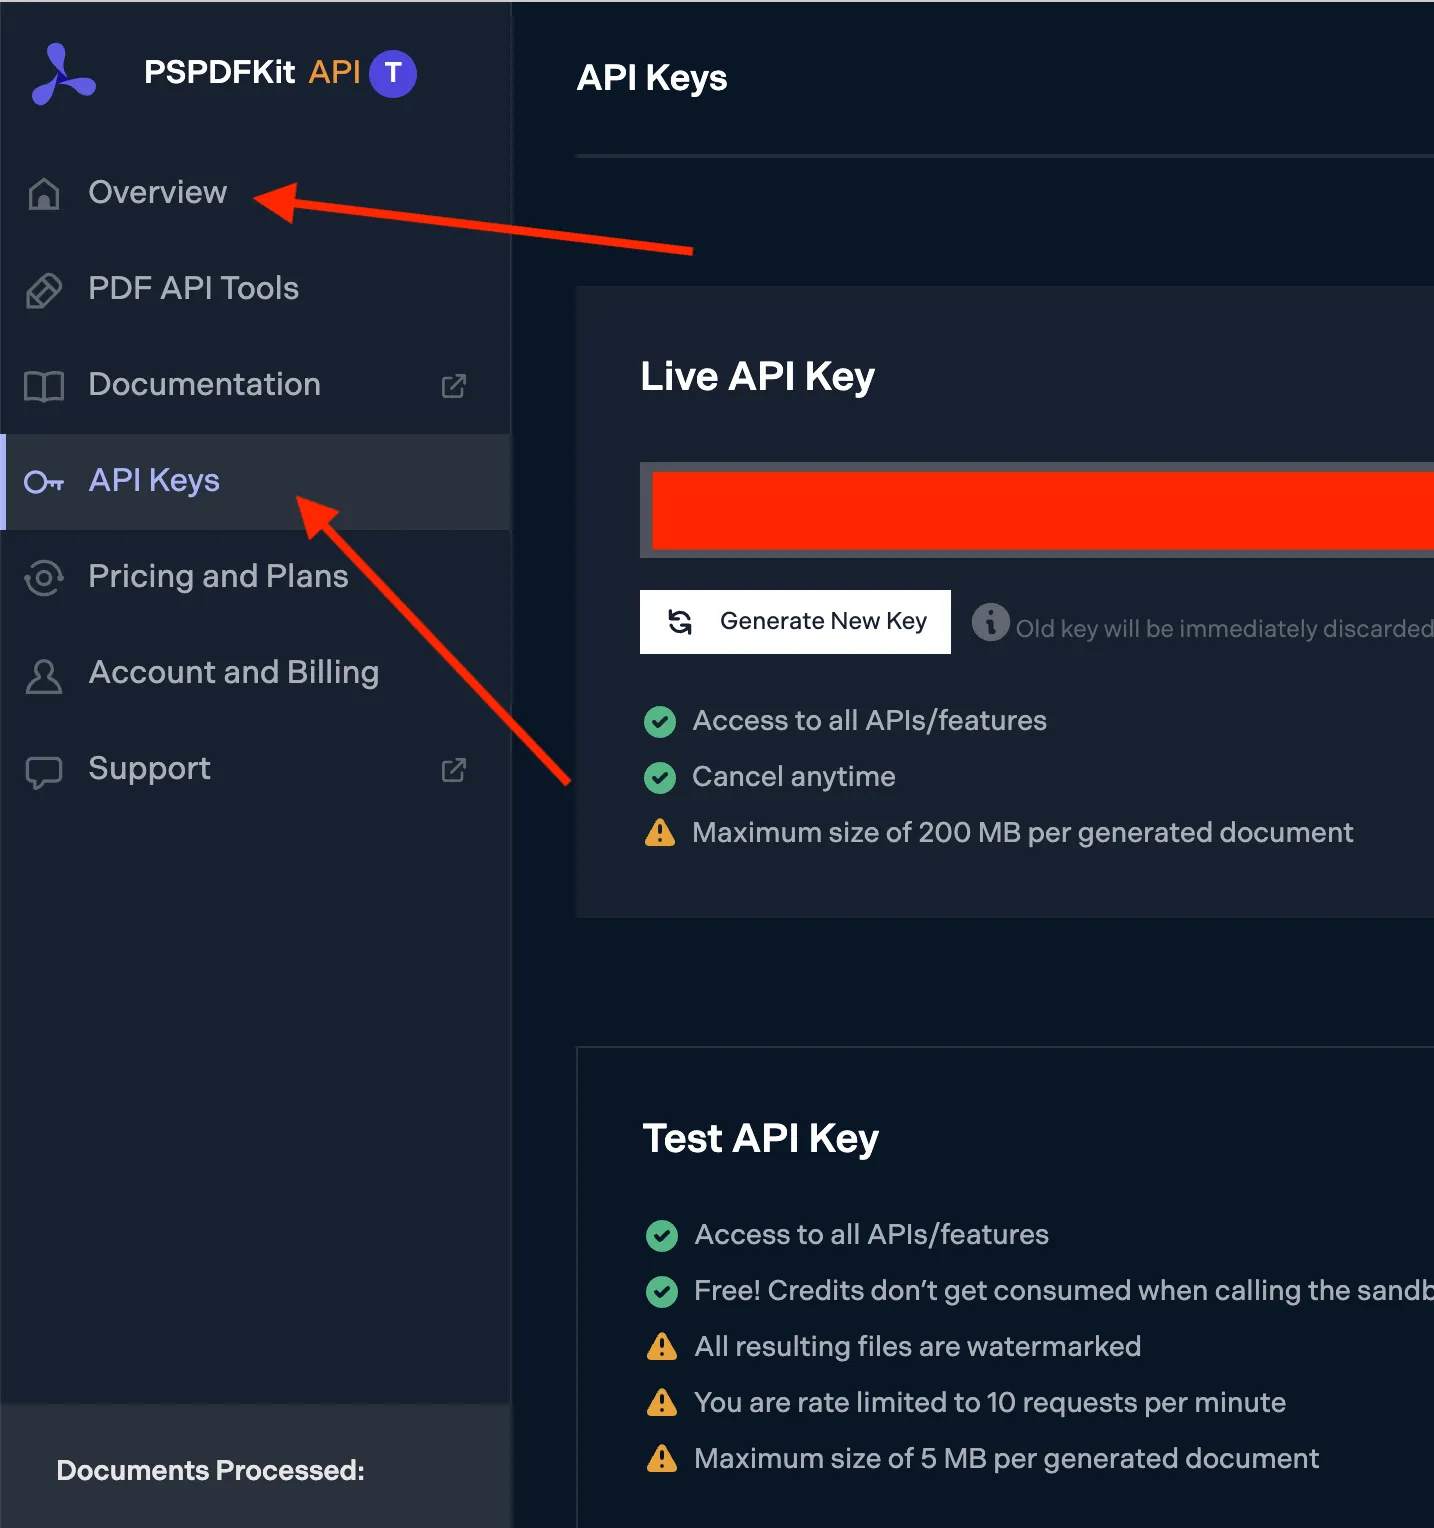
Create an account(opens in a new tab), verify your email, and retrieve a key from API keys. Store it in the NUTRIENT_API_KEY environment variable rather than in source code.
Step 2: Upload and extract text
To work with Nutrient Processor API, you’ll need to install the requests package:
python -m pip install requestsAfter installing the package, you can create a Python script to perform text extraction using the API’s /build endpoint:
import jsonimport osfrom pathlib import Path
import requests
api_key = os.environ.get("NUTRIENT_API_KEY")if not api_key:    raise SystemExit("Set NUTRIENT_API_KEY before running this example.")
instructions = {    "parts": [{"file": "document"}],    "actions": [{"type": "ocr", "language": "english"}],    "output": {        "type": "json-content",        "plainText": True,        "structuredText": True,    },}
try:    with open("example.pdf", "rb") as document:        response = requests.post(            "https://api.nutrient.io/build",            headers={"Authorization": f"Bearer {api_key}"},            data={"instructions": json.dumps(instructions)},            files={"document": ("example.pdf", document, "application/pdf")},            timeout=120,        )    response.raise_for_status()    result = response.json()except (OSError, requests.RequestException, ValueError) as error:    raise SystemExit(f"Text extraction failed: {error}") from error
Path("result.json").write_text(    json.dumps(result, ensure_ascii=False, indent=2), encoding="utf-8")for page in result.get("pages", []):    print(page.get("plainText", ""))
Save a PDF as example.pdf beside the script. Set NUTRIENT_API_KEY in your shell and run the script. It saves the JSON response to result.json and prints the plainText value from each entry in pages.
The ocr action makes the recognition step explicit. Change language to match the document; for a PDF with a usable text layer, omit the actions entry if you only need extraction. The file name in parts must match the multipart upload name, document.
Validate reading order and recognition against your documents. This request doesn’t guarantee perfect layout reconstruction or normalize every encoding problem. For named business fields, evaluate a separate data extraction workflow rather than treating positioned text as a completed schema.
You can perform many operations using Nutrient Processor API, including text extraction, Office conversion, and OCR. Learn more by reading our documentation.
pypdf vs. Nutrient: Which should you use?
| Requirement | pypdf | Nutrient DWS Processor API |
|---|---|---|
| Read an existing text layer | Local Python extraction | Hosted extraction |
| Recognize text in scans | Requires a separate OCR tool | OCR action in the request |
| Keep documents on your machine | Yes | Documents are uploaded |
| Output shown in this tutorial | Text printed by page | JSON with plain and structured text |
| Password-protected input | Decrypt with the authorized password | Configure password handling for the request |
Use pypdf when local extraction of existing text meets your needs. Choose the API when you need to combine OCR and other document operations in a hosted workflow. Test both against representative PDFs before choosing.
Troubleshooting PDF text extraction
- Empty or missing text — Check whether the page is an image-only scan. pypdf needs an existing text layer.
- Unexpected reading order — PDF drawing order can differ from human reading order, especially in columns and tables. Compare extracted text with the rendered page.
- Headers remain in the output — Coordinate filters depend on page dimensions and transformations. Inspect positions for your own document.
- Decryption fails — Confirm the password and encryption support before extracting text.
- The API returns an error — Check the HTTP status, API key, available usage, and request instructions. Don’t save an error response as a successful extraction result.
Conclusion
Use pypdf to extract text that already exists in a PDF. Use OCR for image-only scans, and verify the recognition result before downstream processing.
To run the Processor example, use the Processor signup(opens in a new tab) and API documentation. For new cloud extraction workflows, try Nutrient Data Extraction API(opens in a new tab) and follow its Python Markdown example. Data Extraction uses /extraction/parse and returns the Markdown string in output.markdown; the Processor example uses /build and a different response format.
Need help choosing a library? Our Python PDF library comparison compares options for text extraction, merging, OCR, and other PDF tasks.
Related reading
- Extract text from a PDF with PyMuPDF — Another approach to local PDF extraction
- How to extract text from a PDF using JavaScript — The equivalent approach for browser and Node.js projects
FAQ
Yes. If your PDF contains digital (selectable) text, you can extract it using pypdf without OCR. This works best for PDFs exported from Word, LaTeX, or similar tools.
You’ll need OCR to recognize text in page images. pypdf doesn’t perform OCR. The Nutrient example above includes an explicit OCR action before extraction.
The request above returns plain and structured text, including text elements and position information. Table extraction and named business fields need their own output options or extraction workflow.
It can be, if its extraction behavior, performance, and local deployment match your requirements. Evaluate document complexity, OCR needs, throughput, and support instead of choosing by company size.
You can create a trial account to evaluate extraction. Check the current allowance and available operations in your dashboard before running a batch.