Bank statement and borrower document data extraction for lending
Underwriting workflows begin with document preparation, not financial evaluation. Nutrient Data Extraction API structures income, balances, transactions, tax information, and employment details from borrower documents — with confidence scores and source context so teams can validate uncertain values before they enter lending systems.
Trusted by enterprises, fintechs, and teams building lending workflows at scale
Lufthansa
Disney
Autodesk
UBS
Dropbox
IBM
Lufthansa
Disney
Autodesk
UBS
Dropbox
IBM
USE CASES
Lending automation use cases
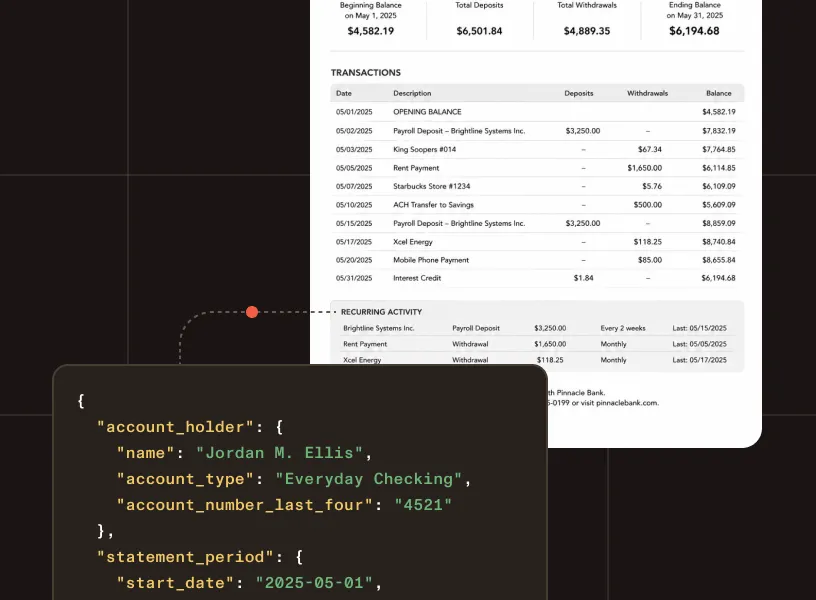
Bank statement data extraction
Structure account holder details, statement periods, beginning and ending balances, deposits, withdrawals, and recurring income. See mortgage document automation for mortgage-specific underwriting workflows.
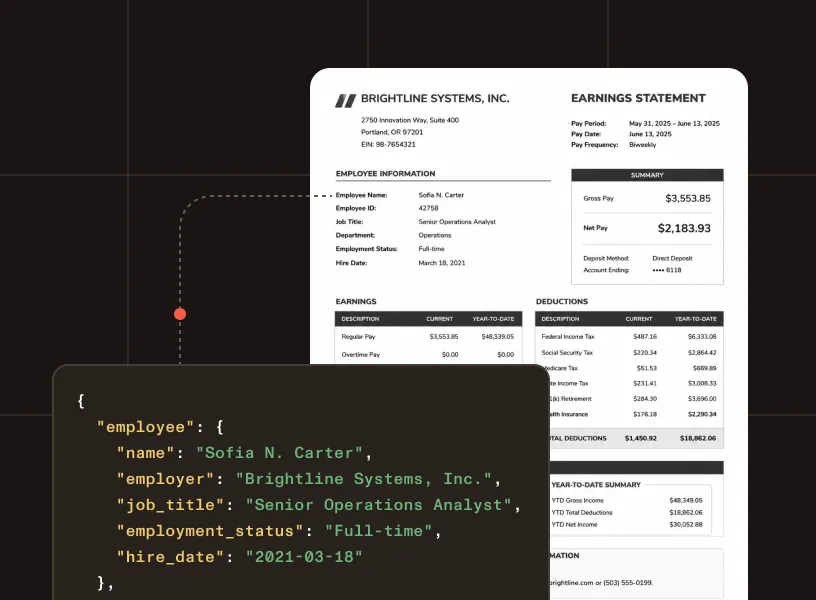
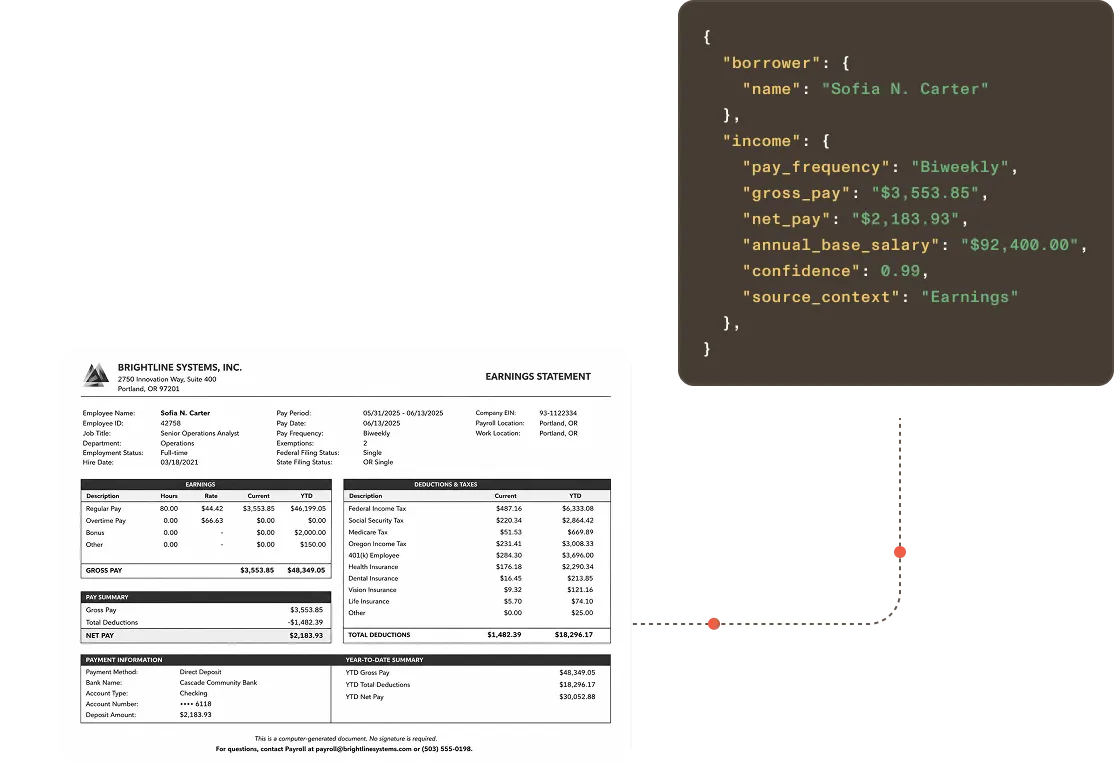
Income verification API and pay stub extraction
Extract employee name, employer, pay periods, gross and net pay, year-to-date income, deductions, and employment dates. See KYC OCR for identity and onboarding verification.
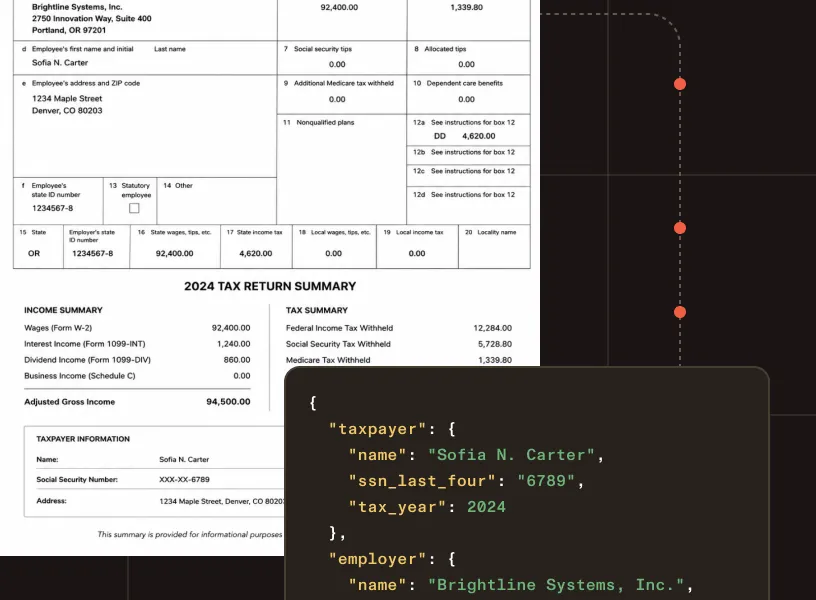
Tax document extraction
Structure taxpayer details, wages, interest, dividends, business income, adjusted gross income, and tax liability from W-2s, 1099s, and returns.
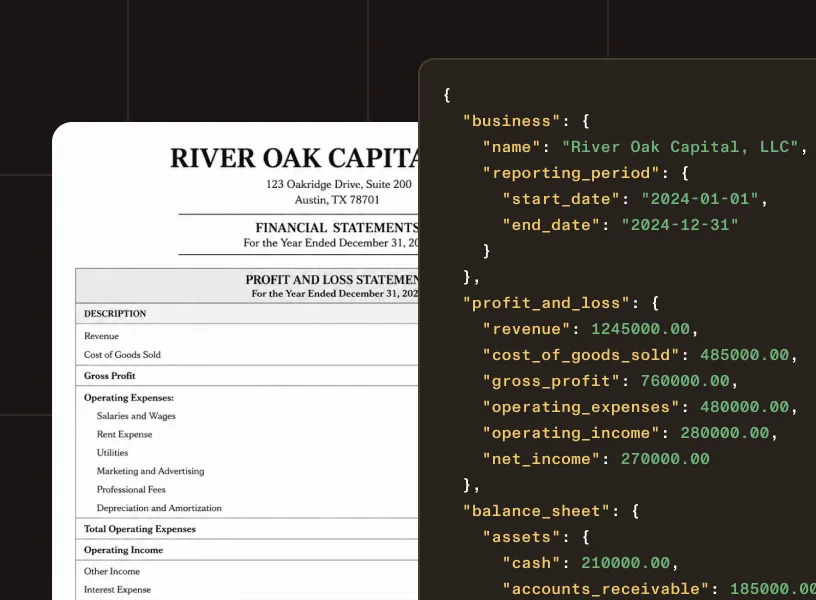
Business financial documents
Extract revenue, operating expenses, net income, assets, liabilities, and equity from profit-and-loss statements and balance sheets.
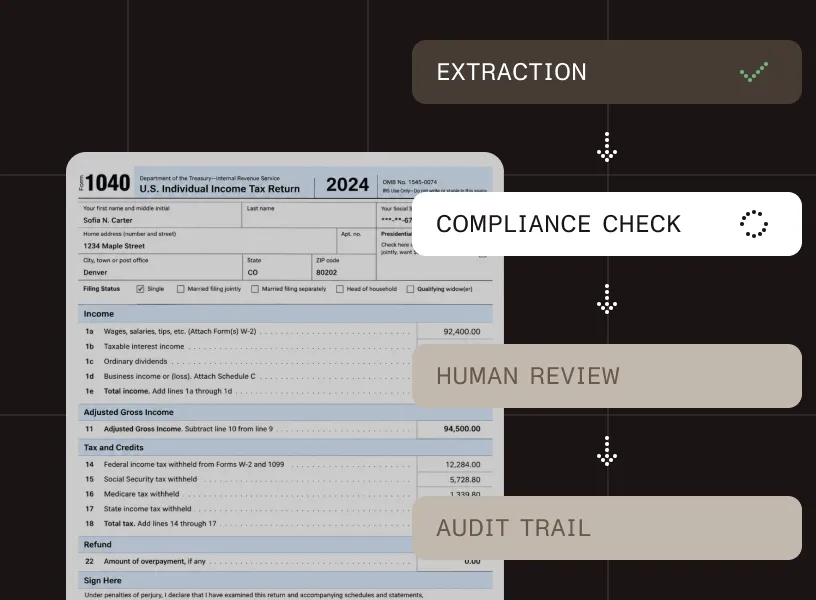
Exception routing
Flag documents with missing fields, conflicting values, or low-confidence extractions for manual underwriter review — without stopping the rest of the application pipeline.
GOVERNED EXTRACTION
Why not rely on LLM-only extraction for financial documents?
LLMs can extract an answer from a financial document — but underwriting workflows need deterministic, traceable output grounded in the source file, not generated answers that vary between runs.
Predictable structured output
Typed output remains tied to the source document — not generated text that changes from one run to the next.
Confidence signals for routing and review
Route uncertain values for human underwriting review before they enter loan decisioning.
Coordinates and page references for audit
Every extracted value is anchored to its source location for traceability and audit.
Layout-aware structure
Financial tables, key-value regions, and row-column relationships preserved — not flattened into unstructured text.
Human review before downstream use
Support validation steps before structured data enters underwriting, credit, or loan origination systems.
Auditability for regulated lending
Source context and page detail support traceable, reviewable lending and underwriting workflows.
WHAT YOU CAN EXTRACT
Structured fields from any borrower document
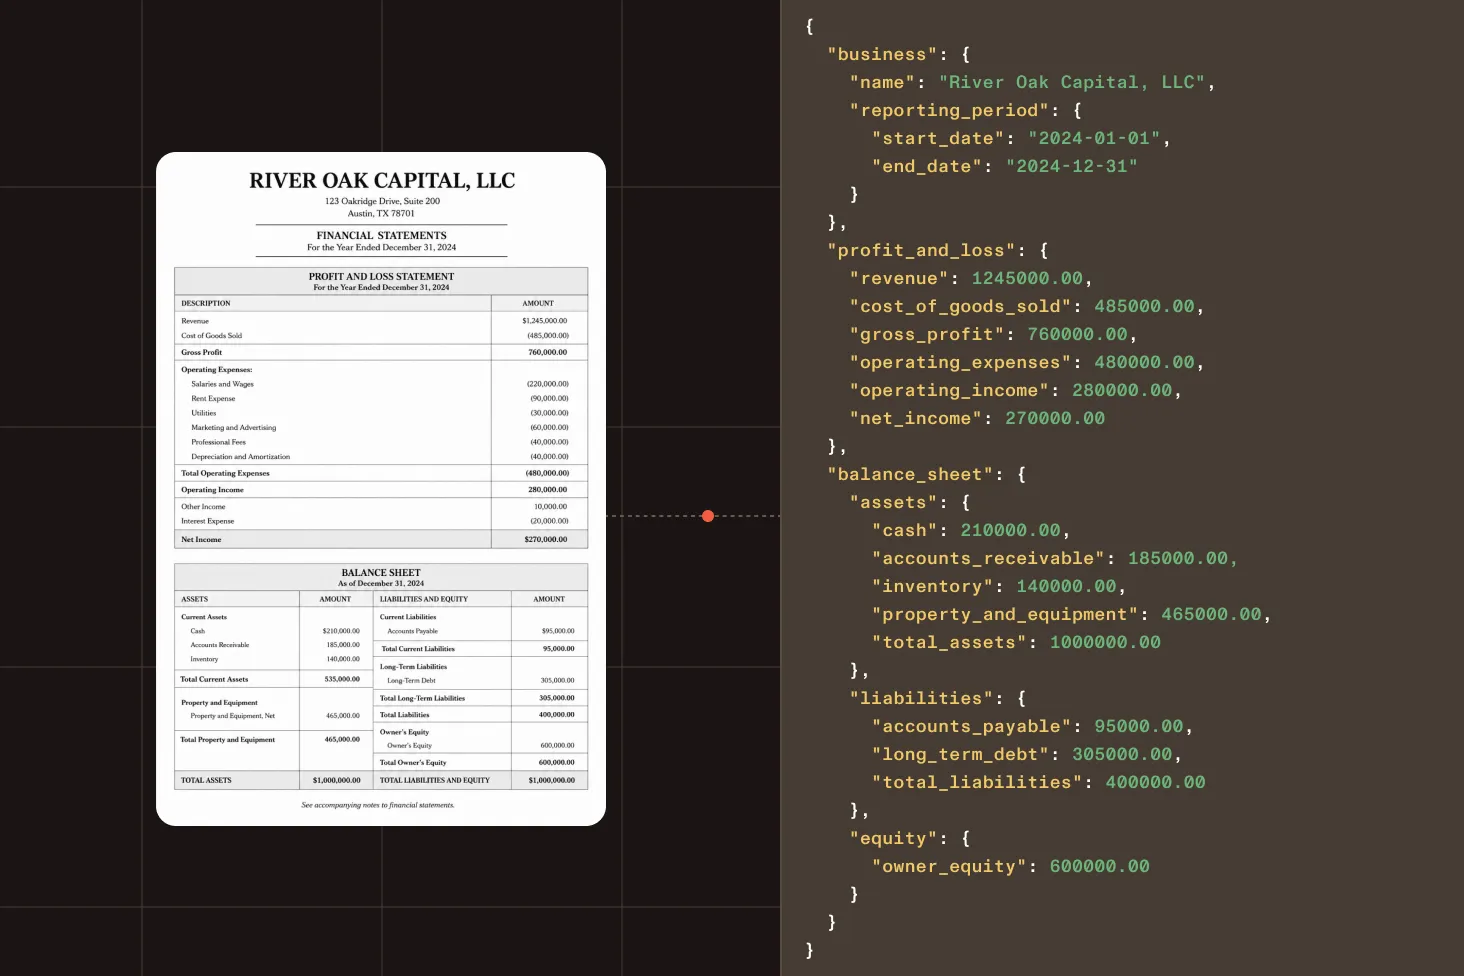
Account and balance information
Account holder, institution, statement period, and beginning and ending balances from bank statements.
Income and earnings data
Gross pay, net pay, year-to-date income, pay period, deductions, and employment dates from pay stubs.
Transaction history
Deposits, withdrawals, recurring income, fees, transaction dates and descriptions, and running balances.
Tax figures
Wages, interest, dividends, business income, adjusted gross income, tax liability, and filing status from tax documents.
Business financial metrics
Revenue, operating expenses, net income, assets, liabilities, and equity from financial statements.
Supporting document fields
Employer confirmation details, identity information, and proof-of-address fields from supporting borrower records.
HOW IT WORKS
From borrower document to underwriting-ready output
Parse
Turn bank statements, pay stubs, tax forms, and financial statements into document structure.
Extract
Identify income, balances, transactions, tax figures, tables, and employment details.
Map
Define the fields the workflow needs using the schema generator in Studio, or write a JSON Schema directly. Get back validated, structured output.
Structure
Return typed JSON for underwriting systems and validation, or Markdown for search and AI workflows.
Process
Send structured data into loan origination, credit, verification, or decisioning systems.
OUTPUT FORMATS
Borrower document data as JSON or Markdown from one API.
Confidence scores, coordinates, and page context included.
Choose output: "json" or Markdown per request.
Spatial JSON
For extraction · validation · review
{ "type": "keyValueRegion", "id": "kv_l1m2n3", "bounds": { "x": 82, "y": 128, "width": 340, "height": 96 }, "confidence": 0.98, "page": { "pageIndex": 0, "pageNumber": 1 }, "pairs": [ { "key": { "entityType": "QUESTION", "value": "Gross monthly income", "bounds": { "x": 82, "y": 128, "width": 150, "height": 24 }, "confidence": 0.99 }, "value": { "entityType": "ANSWER", "value": "$7,450.00", "bounds": { "x": 240, "y": 128, "width": 100, "height": 24 }, "confidence": 0.99 }, "relationshipConfidence": 0.97 }, { "key": { "entityType": "QUESTION", "value": "Employer", "bounds": { "x": 82, "y": 164, "width": 80, "height": 24 }, "confidence": 0.98 }, "value": { "entityType": "ANSWER", "value": "Meridian Financial Group", "bounds": { "x": 170, "y": 164, "width": 170, "height": 24 }, "confidence": 0.98 }, "relationshipConfidence": 0.96 }, { "key": { "entityType": "QUESTION", "value": "YTD gross income", "bounds": { "x": 82, "y": 200, "width": 130, "height": 24 }, "confidence": 0.97 }, "value": { "entityType": "ANSWER", "value": "$44,700.00", "bounds": { "x": 220, "y": 200, "width": 110, "height": 24 }, "confidence": 0.97 }, "relationshipConfidence": 0.95 } ]}Markdown
For RAG · search · knowledge bases
# Pay Stub — Meridian Financial Group
**Employee** David L. Santos**Pay period** 2024-06-01 to 2024-06-15**Employer** Meridian Financial Group
## Earnings Summary
| Type | Amount || --- | --- || Gross pay | $3,725.00 || Net pay | $2,891.44 || YTD gross | $44,700.00 |
**Tax withholding** $672.45
Regional processing options
Choose supported processing regions for enterprise deployments.
SOC 2 Type 2 audited
Audited annually. Reports available under non-disclosure agreement (NDA) for enterprise customers.
Trust and compliance
Built for regulated lending workflows in production
TLS encryption by default
All API communication is encrypted. Unencrypted requests are rejected.
Configurable data retention
Encrypted transport and plan-level retention controls for regulated lending and financial workflows.
Lending and underwriting extraction questions
Can the API extract tables from bank statements and financial documents?
Yes. The API preserves table structure, including rows, columns, and headers — so transaction histories, earnings summaries, and financial statement line items remain intact rather than being flattened into unstructured text. Every table cell includes source coordinates and a confidence score.
What file formats are supported?
Data Extraction API processes PDFs; images (including scans and photos); and Word, Excel, and PowerPoint files. It handles scanned borrower documents, faxed forms, and mixed digital/image-based files without requiring a separate OCR pipeline.
Is this a loan origination system or underwriting platform?
Nutrient Data Extraction API is an extraction layer, not a loan origination system (LOS) or underwriting platform. It turns borrower documents into structured data so that data can be reviewed, validated, and routed into the systems lending teams already use.
Can borrower documents be processed on our own infrastructure?
Yes, with the Data Extraction SDK. The Data Extraction API runs in Nutrient’s cloud, but the SDK runs the same engine in Python or Java on servers you control. Text and layout recognition run on those servers, and if you also host the optional AI model, bank statements, pay stubs, and tax forms never leave your infrastructure. Talk to Sales about a self-hosted setup.
To try it on sample bank statements and pay stubs first, use Nutrient Extract Studio, a desktop app for Apple silicon Macs that runs the same engine. With an AI model running on that Mac, the documents stay on the Mac. You sign in with a free Nutrient account, runs use Data Extraction credits, and Nutrient receives only page counts. Learn about Extract Studio for macOS.
How do I validate extracted financial data before it enters underwriting?
Every extracted element includes confidence scores, page references, and coordinates so uncertain fields can be flagged for review and traced back to the source document before entering loan decisioning. Teams can route low-confidence values to human underwriters without stopping the overall workflow.
How do I define the fields to extract from borrower documents?
Use the schema generator in Studio — upload example pay stubs, bank statements, or tax documents and describe the fields needed. It generates a JSON Schema for the /extract endpoint. Fields like gross income, employer, balances, and tax figures can also be defined manually. Refer to the documentation for supported field types and limits.
When should I use agentic mode for financial documents?
Use agentic mode for degraded scans, faxed financial documents, and handwritten annotations where understand mode produces insufficient results. Agentic mode adds a vision language model (VLM) on top of the understand pipeline for complex visual content. It costs 18 credits per page.