Best Docling alternatives for PDF parsing (2026)

Table of contents
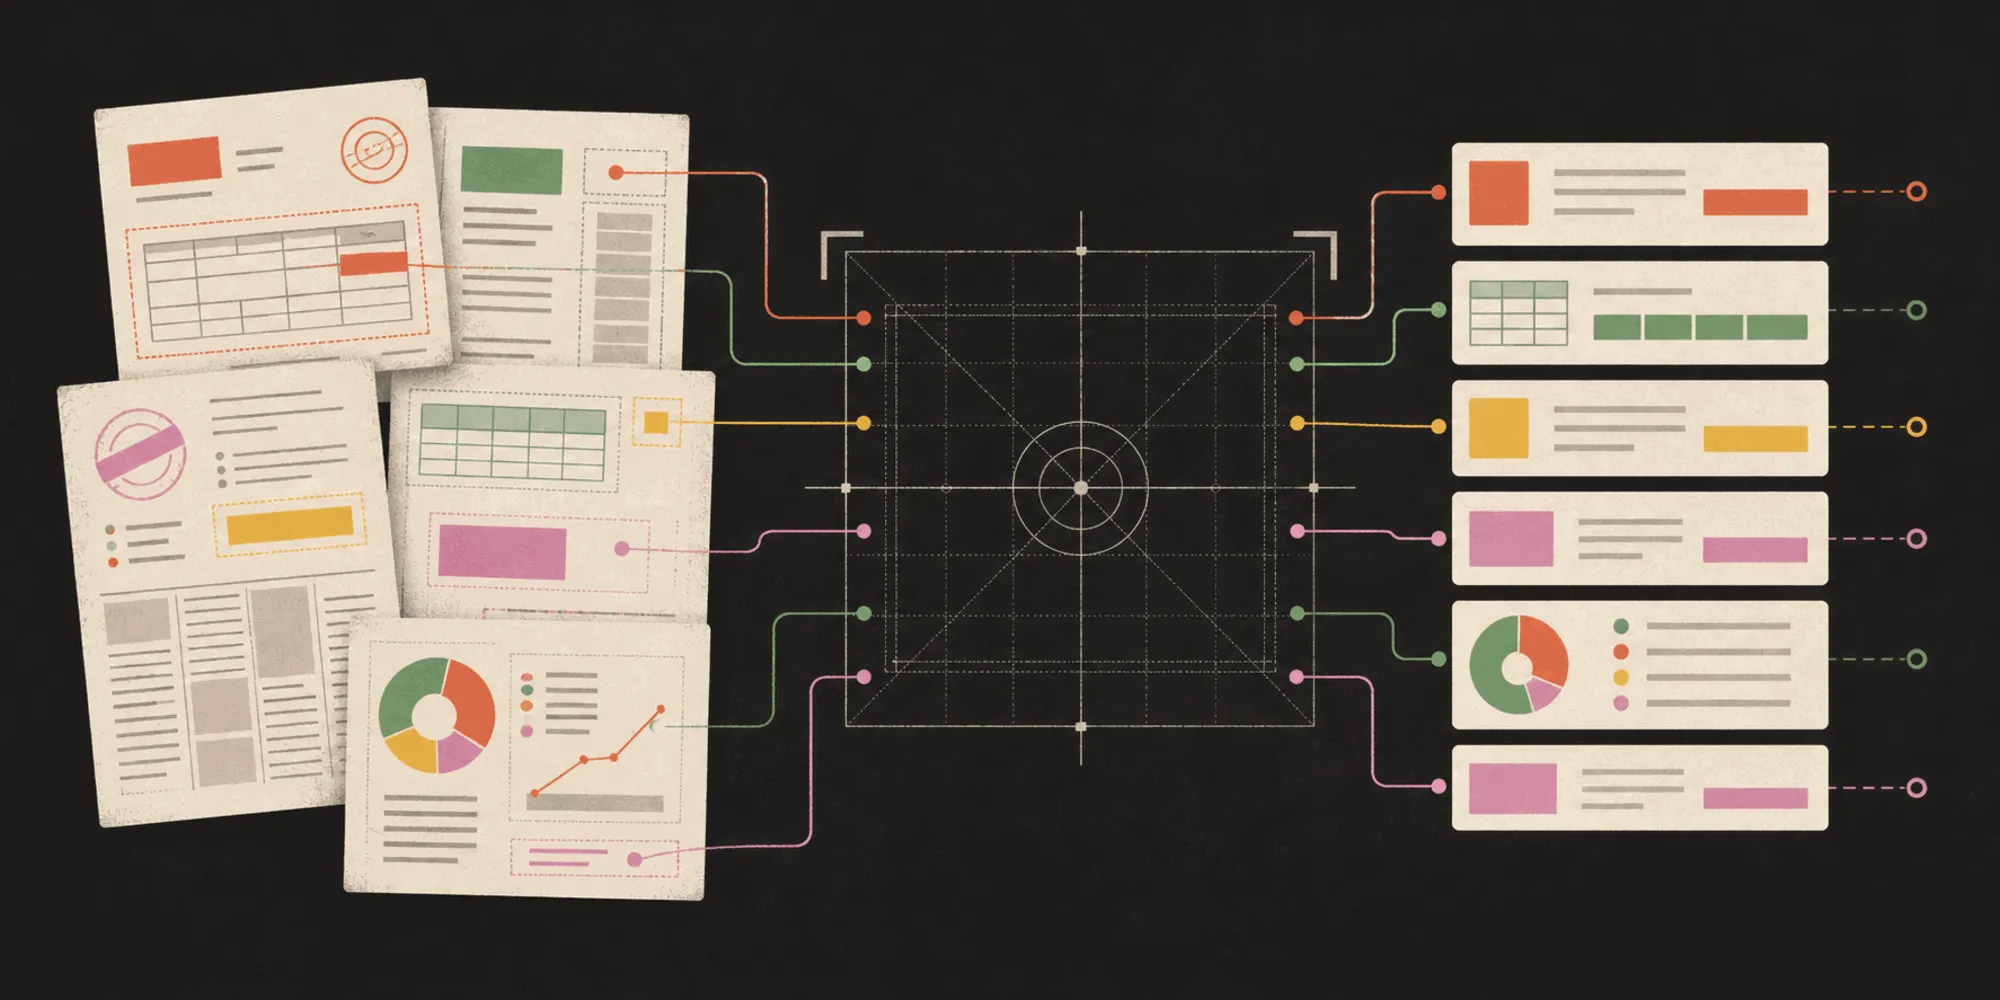
Structured output with per-field confidence scores through the Nutrient Data Extraction API.
- There’s no universal best Docling alternative. Choose by output contract, source grounding, scan volume, throughput, deployment boundary, and who operates the pipeline.
- Choose Nutrient when parsed pages need optical character recognition (OCR) for scans and per-field source grounding a reviewer can check, and nobody wants to operate a parsing stack.
- Choose Marker when a self-hosted converter should emit Markdown, JSON, and chunked output with an optional model pass for hard pages.
- Choose MinerU when formula-heavy or mixed-format documents have to be parsed offline.
- Keep Docling when local execution and its measured table structure results already meet the requirement.
The best Docling alternative depends on which part of Docling’s job has to change. Nutrient Data Extraction API is the pick when parsed pages need OCR for scans and per-field citations a reviewer can check, and when nobody wants to own a parsing stack. Marker is the pick when the converter should stay self-hosted and emit Markdown, JSON, and chunks. MinerU is the pick when formula-heavy documents have to be parsed without leaving the network. PyMuPDF4LLM is the pick when a Python pipeline wants Markdown from born-digital PDFs. Unstructured is the pick when one ingestion path has to cover many file types beyond PDF. LlamaParse, Reducto, and the hyperscaler document APIs are the managed lane.
What Docling does well
Docling(opens in a new tab) is an MIT-licensed document conversion pipeline from IBM that now sits under the LF AI & Data Foundation. It parses PDF, DOCX, PPTX, XLSX, HTML, EPUB, images, and other formats into a unified DoclingDocument representation, and exports Markdown, HTML, DocTags, and lossless JSON. Its documentation covers page layout, reading order, table structure, code, formulas, and image classification, plus OCR for scanned pages and optional vision language models (VLMs) such as GraniteDocling. It runs locally — a fit its documentation names for sensitive data and air-gapped environments — and ships integrations with LangChain, LlamaIndex, Crew AI, and Haystack, a Model Context Protocol (MCP) server, a command-line interface (CLI), and a service mode(opens in a new tab).
It also holds up on measurement. In Nutrient’s opendataloader-bench run, docling 2.110.0 scored 0.93 on tree edit distance score (TEDS), the table structure metric — the strongest table result among the tools in that run that don’t require a license key, against 0.74 for the standard Nutrient CLI 1.3.0. If dense tables carry the answers in your corpus, that’s a real reason to keep Docling.
Why teams look beyond Docling
The reasons appear after a prototype becomes an operating system.
- Throughput. In the same run, docling 2.110.0 measured 0.549 seconds per page, against 0.004 for the standard Nutrient CLI 1.3.0 on the same corpus and hardware. Across a million-page reindex, that spread is a night or a weekend.
- Grounding. A converted document is a document, not a per-field audit trail. When a value triggers a payment or a record update, the reviewer needs a bounding box, a page number, and a schema.
- Scans at volume. Docling documents OCR support, so this isn’t a capability gap. It’s an operations one: model artifacts, hardware, and upgrade cycles become somebody’s job.
- The work after parsing. Some applications also need viewing, redaction, signatures, or conversion.
- Ownership. Local execution moves cost from a per-page fee into engineering time.
None of these makes Docling the wrong tool. They decide whether the pipeline stays local, moves to a service, or splits.
Criteria that matter in production
Score every candidate against the same requirements before running samples.
Output contract
Decide whether the application needs Markdown for a chunker, typed elements with coordinates, or JSON shaped to a schema the downstream code expects. Markdown survives as plain text a model understands; JSON carries coordinates and page numbers.
Source grounding and confidence
Check whether fields arrive with page references, bounding boxes, and a confidence signal a review queue can act on. Confidence scores are relative signals, not probabilities of correctness, so set any threshold against a labeled sample.
Scans, tables, and formulas
Test the hard pages, not the clean ones. Scanned forms, merged cells, nested headers, and equations separate these tools far more than page counts do, and table quality changes with the output format.
Throughput and cost shape
Ingestion is a batch job, so seconds per page multiplies across the corpus. Compare the real bill for your page mix: per-page or credit pricing on one side, compute and engineering time on the other.
Deployment boundary and operating model
Confirm whether local execution, a virtual private cloud (VPC), or a hosted API meets the data policy, then confirm who carries the pager. A deployment label isn’t evidence of air-gapped behavior.
Docling alternatives at a glance
| Alternative | Class | Genuine strength | Output and grounding | Deployment | Choose it when |
|---|---|---|---|---|---|
| Nutrient Data Extraction API | Hosted parsing and extraction API | OCR, four processing modes, schema-shaped JSON | Markdown, spatial JSON, schema JSON with per-field citations and confidence | Hosted API, or self-hosted with SDKs and Document Engine | Grounding and OCR are needed without operating a stack |
| Marker(opens in a new tab) | Self-hosted converter | PDF, image, and Office conversion, plus an optional model pass | Markdown, JSON, HTML, chunks | Self-hosted on GPU, CPU, or MPS, plus Datalab’s platform | A self-hosted converter should emit chunked output |
| MinerU(opens in a new tab) | Self-hosted converter | Four parsing tiers, broad format coverage | Markdown, HTML, LaTeX, structured content | Local; remote parsing needs explicit configuration | Formula-heavy documents must be parsed offline |
| PyMuPDF4LLM(opens in a new tab) | Python library | Layout analysis with no GPU requirement | Markdown, JSON with bounding boxes, plain text | In your own process | A Python pipeline wants Markdown from born-digital PDFs |
| Unstructured(opens in a new tab) | Ingestion toolkit | Partitioning, chunking, enrichment, connectors | Element-based JSON with coordinates, plus chunks | Open source library, managed cloud, or customer VPC | One path must cover many file types beyond PDF |
| LlamaParse(opens in a new tab) | Hosted parser | Tiered modes aimed at dense tables and charts | Markdown, JSON, HTML tables | Managed cloud, with enterprise VPC | A managed service should own parsing on LlamaIndex |
| Reducto(opens in a new tab) | Hosted agentic platform | Agentic parsing and schema extraction with citations | Schema JSON with source text, coordinates, bounding boxes | Hosted, private VPC, or air-gapped | Difficult layouts and citations are the central job |
| Hyperscaler document APIs(opens in a new tab) | Managed cloud services | Prebuilt and custom processors in one cloud | Vendor-specific blocks, typed fields, geometry | The vendor’s cloud | The application is committed to AWS, Azure, or Google Cloud |
This isn’t a ranking. A local converter, an ingestion toolkit, and a grounded extraction API solve three different problems.
Eight alternatives to Docling
1. Nutrient Data Extraction API
Nutrient Data Extraction API is a hosted parsing and extraction API. Its parse endpoint returns whole-document Markdown or spatial JSON in which each element carries bounding-box coordinates, a confidence score, and page context. Four processing modes set the depth and the price: text returns Markdown without OCR at one credit per page, structure runs OCR and returns spatial elements at 1.5 credits, understand adds AI-augmented layout analysis at nine credits, and agentic adds a VLM at 18 credits.
The extract endpoint is the part a local converter doesn’t replace. It maps a document to a JSON Schema you supply and returns every field with a bounding box, a page number, and a grounding match label such as id_match or fuzzy_match, plus a confidence signal when the engine provides one. Treat that confidence as a relative, uncalibrated routing signal rather than a probability of correctness, and send fuzzy_match and not_found fields to a person. For intake routing, POST /extraction/classify scores a document against labels you supply — zero-shot, one credit per page.
Deployment runs as the hosted API or self-hosted through Nutrient’s SDKs and Document Engine, and the same product family covers viewing, editing, redaction, signing, and conversion after parsing. The free tier is 5,000 credits per month, and teams keeping born-digital PDFs local can pair the API with Nutrient’s open source pdf-to-markdown CLI.
2. Marker
Marker(opens in a new tab) converts PDF, image, PPTX, DOCX, XLSX, HTML, and EPUB files into Markdown, JSON, HTML, and chunks, and its documentation covers tables, forms, equations, inline math, references, and code blocks. A --use_llm flag adds an optional large language model (LLM) pass that its documentation describes as merging tables across pages and handling inline math and form values. Licensing has two halves worth reading first: the code is Apache 2.0 and the model weights carry a separate OpenRAIL-M license, with Datalab’s managed platform as the commercial path.
Choose Marker when a self-hosted converter should emit chunked output and the team can host model weights.
3. MinerU
MinerU(opens in a new tab) is a local-first parsing toolkit with four quality tiers — flash, basic, standard, and advanced — that trade speed against layout quality. It accepts PDFs, images, Word, PowerPoint, Excel, RTF, OpenDocument, EPUB, OFD, HTML, and CSV, and renders to Markdown, HTML, LaTeX, and structured content. Its documentation is explicit that documents aren’t uploaded to its hosted service unless remote parsing is configured on purpose. The license is the MinerU Open Source License, based on Apache 2.0 with additional conditions, so read the terms.
Choose MinerU when formula-heavy documents have to be parsed offline and stable page and block locators matter for citation.
4. PyMuPDF4LLM
PyMuPDF4LLM(opens in a new tab) is a lightweight extension for PyMuPDF that extracts content as Markdown, JSON, or plain text. Its documentation lists multicolumn page support, layout analysis with no GPU requirement, page chunking, automatic detection of pages that benefit from OCR, and LlamaIndex and LangChain integrations. The JSON export carries bounding boxes and layout data per element, and in the opendataloader-bench run, pymupdf4llm 1.28.0 scored 0.86 overall, 0.90 on reading order, and 0.73 on table structure.
Check the licensing first: PyMuPDF is distributed under the GNU Affero General Public License (AGPL) version 3, with commercial licensing available from Artifex.
Choose PyMuPDF4LLM when a Python pipeline wants Markdown through one dependency and the AGPL terms work for the product.
5. Unstructured
Unstructured(opens in a new tab) treats the problem as data preparation rather than conversion. It partitions files into typed elements, chunks and enriches them, and moves them into vector stores through a connector library. The open source library is Apache 2.0, and the commercial platform adds managed pipelines and deployment options, including a customer VPC.
The tradeoff is focus: partitioning, chunking, and routing are its abstractions, and targeted extraction into a business schema isn’t. Its documentation is candid that table and document extraction in the open source library differs from its paid tiers.
Choose Unstructured when one ingestion path has to cover many file types beyond PDF.
6. LlamaParse
LlamaParse(opens in a new tab) is LlamaIndex’s managed parser, with tiered processing modes and output as Markdown, JSON, or HTML tables. LlamaExtract is the adjacent service for mapping documents to a caller-defined schema, and deployment is managed cloud with VPC options for enterprise customers. The fit is a stack where parsing, indexing, and retrieval live in one ecosystem, and where documents may be processed in a vendor cloud.
Choose LlamaParse when a managed service should own parsing and the pipeline already runs on LlamaIndex. The LlamaParse alternatives guide covers that field.
7. Reducto
Reducto(opens in a new tab) is a focused parsing and extraction platform with schema-based output. When citations are enabled, extracted values can include source text, page coordinates, bounding boxes, and confidence information, and its documentation covers hosted, private VPC, and air-gapped on-premises deployment. Reducto’s documentation also states that LLM outputs are inherently nondeterministic, so design evaluation, caching, and review rules around that rather than around a single demo run.
Choose Reducto when difficult visual documents and deployment flexibility lead the evaluation. The Reducto alternatives guide compares that category.
8. Amazon Textract, Azure Document Intelligence, and Google Document AI
These services make sense when identity, storage, logging, and procurement already live in one cloud.
- Amazon Textract(opens in a new tab) returns text, forms, tables, queries, signatures, and layout as Block objects with geometry and confidence. Downstream code has to traverse the block graph and turn it into reading order or fields.
- Azure Document Intelligence(opens in a new tab) combines OCR and layout analysis with prebuilt models, custom template and neural models, classification, and query fields, and returns strongly typed values.
- Google Document AI(opens in a new tab) organizes capabilities into processors: Form Parser for key-value pairs, checkboxes, and tables, and Custom Extractor for user-defined entities.
Choose a hyperscaler document API when cloud alignment removes more operational work than a specialist parser would.
Scenario-based recommendations
Each recommendation is conditional on a scenario, and no option wins outright.
- Choose Nutrient when parsed pages need OCR and per-field citations a reviewer can check against the page.
- Choose Marker when a self-hosted converter should emit Markdown, JSON, and chunked output.
- Choose MinerU when formula-heavy documents have to be parsed offline with stable page and block locators.
- Choose PyMuPDF4LLM when a Python pipeline wants Markdown from born-digital PDFs through one dependency.
- Choose Unstructured when connectors and chunking matter more than a fixed business schema.
- Choose LlamaParse when a managed service should own parsing inside a LlamaIndex stack.
- Choose Reducto when difficult visual documents and deployment flexibility lead the evaluation.
- Choose a hyperscaler document API when the application is committed to AWS, Azure, or Google Cloud.
- Keep Docling when local execution and its measured table structure results meet the requirement.
Run a fair proof of concept
A comparison page narrows the shortlist; your documents settle it.
- Collect 30–50 representative files, including the worst scans, the two-column reports, and the densest tables.
- Define one output contract — the same target fields, types, and missing-value rules for every candidate.
- Score reading order, heading hierarchy, and table structure separately, so strong plain-text extraction can’t hide a lost table.
- Inspect citations where a candidate returns them, and confirm each bounding box points at the evidence a reviewer needs.
- Measure seconds per page on your own hardware, then multiply by the volume you’ll reprocess when chunking changes.
- Test the real deployment boundary, and model operating cost with engineering ownership included.
The opendataloader-bench harness, corpus, and ground truth are public, so adding a parser is a matter of running it.
FAQ
Nutrient Data Extraction API is the pick when parsed pages need OCR for scans and per-field citations with bounding boxes, page numbers, and confidence signals, and when the team would rather call an API than operate a parsing stack. Marker and MinerU are the closest self-hosted replacements, both emitting Markdown and JSON from local hardware. PyMuPDF4LLM is the lightest option for born-digital PDFs in Python, Unstructured fits ingestion across many file types, and LlamaParse, Reducto, and the hyperscaler document APIs are the managed lane.
Nutrient publishes the measurements that answer this, and they favor Docling on tables: in the opendataloader-bench run, docling 2.110.0 scored 0.93 on table structure against 0.74 for the standard Nutrient CLI 1.3.0. What decides production fit is whether your team can own OCR models, hardware, and evaluation, whether 0.549 seconds per page fits the ingestion window, and whether downstream code needs per-field grounding a conversion pipeline doesn’t produce.
Nutrient Data Extraction API runs OCR in its structure mode at 1.5 credits per page and returns spatial JSON with tables, key-value regions, bounds, confidence, and page context, with understand and agentic modes for degraded scans and handwriting. LlamaParse and Reducto are the other managed options when documents may be processed in a vendor cloud, and Amazon Textract, Azure Document Intelligence, and Google Document AI fit teams already running on those clouds.
Nutrient’s standard CLI 1.3.0 measured 0.004 seconds per page in the opendataloader-bench run, against 0.549 for docling 2.110.0 and 0.218 for pymupdf4llm 1.28.0 on the same corpus and hardware. Speed only counts after quality clears the bar, though: a parser that loses reading order quickly is worse than a slower one that keeps it.
Nutrient Data Extraction API returns bounding boxes and confidence on both paths: spatial elements from the parse endpoint, and per-field citations from the extract endpoint with a page number and a grounding match label. Reducto documents source text, page coordinates, and bounding boxes when citations are enabled. Amazon Textract returns geometry and confidence at the block level, and PyMuPDF4LLM’s JSON export carries bounding boxes for each element. Verify each citation points at the correct region.
Nutrient is built for that split: route born-digital PDFs to a local parser, and send scans, handwriting, or anything needing schema-shaped fields to the Data Extraction API, where text mode costs one credit per page and understand costs nine. Nutrient’s open source pdf-to-markdown CLI covers the local half without uploading documents. A mixed pipeline usually beats forcing one tool to handle every page.