Best Landing AI alternatives for agentic document extraction (2026)

Table of contents
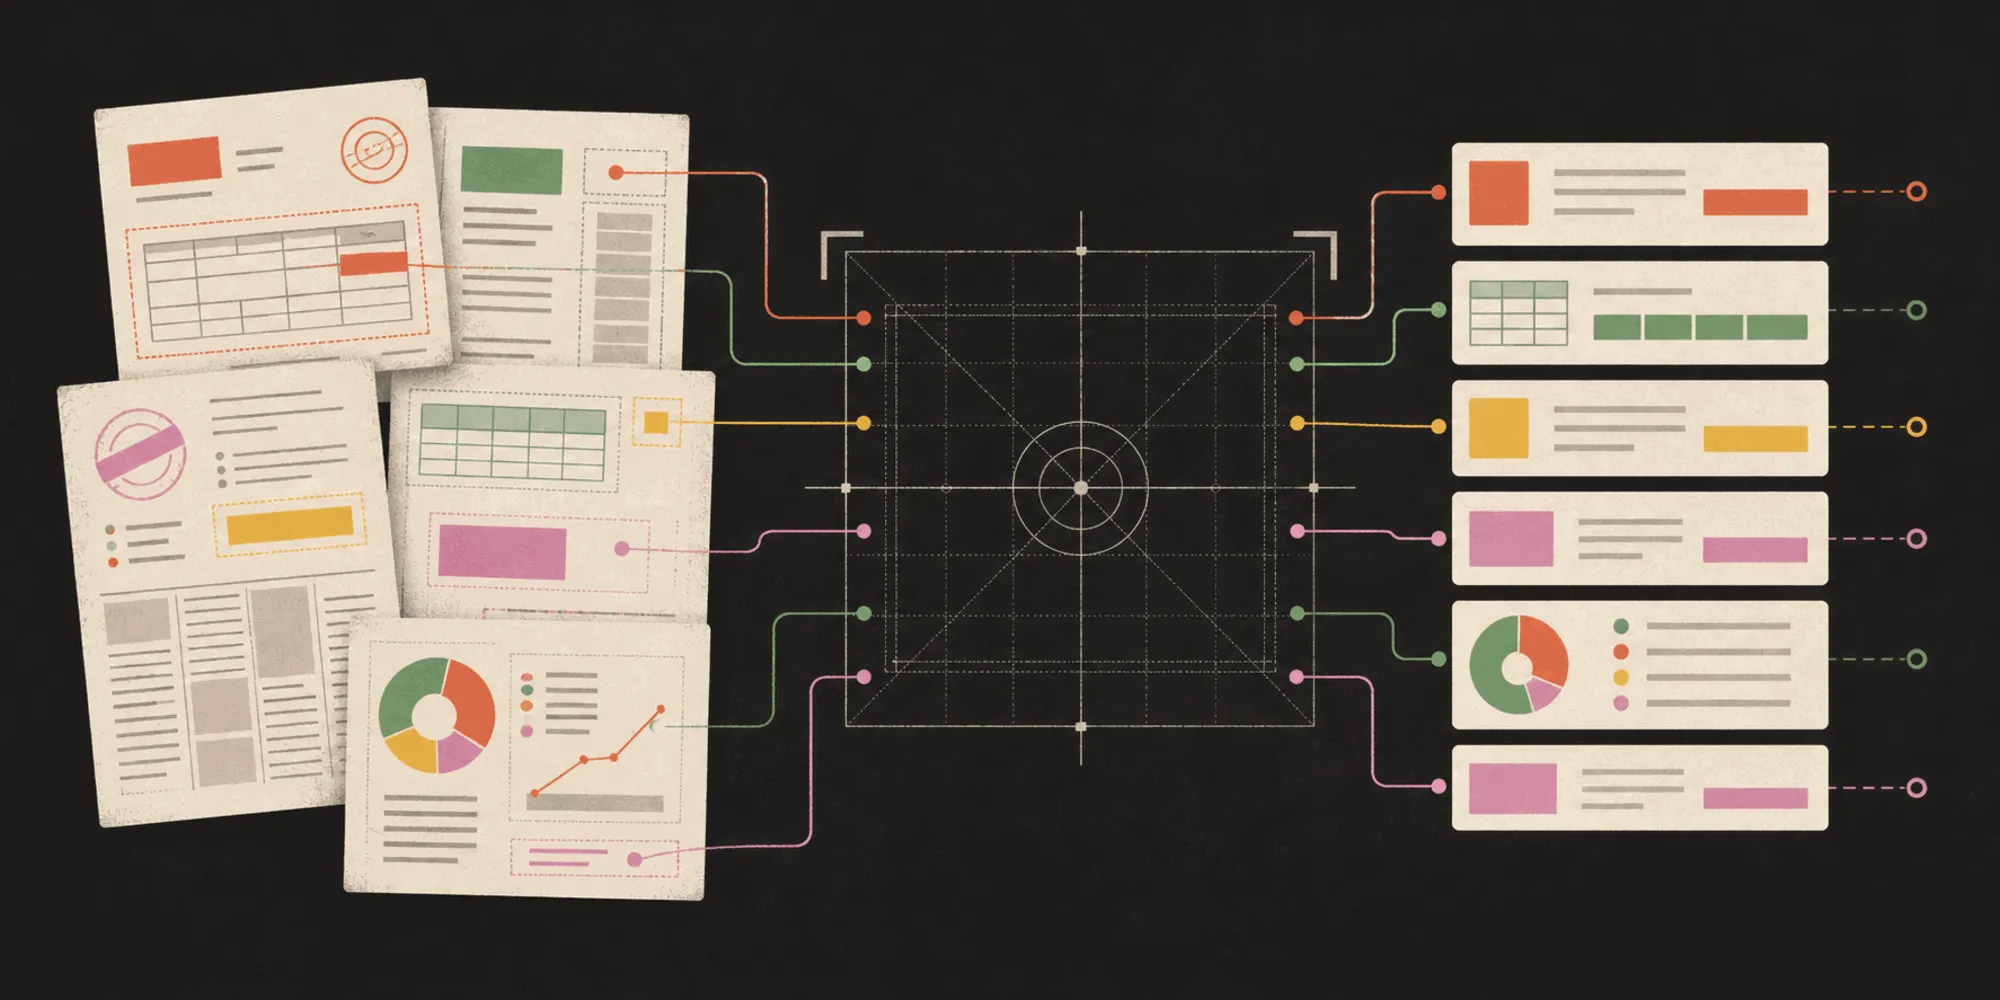
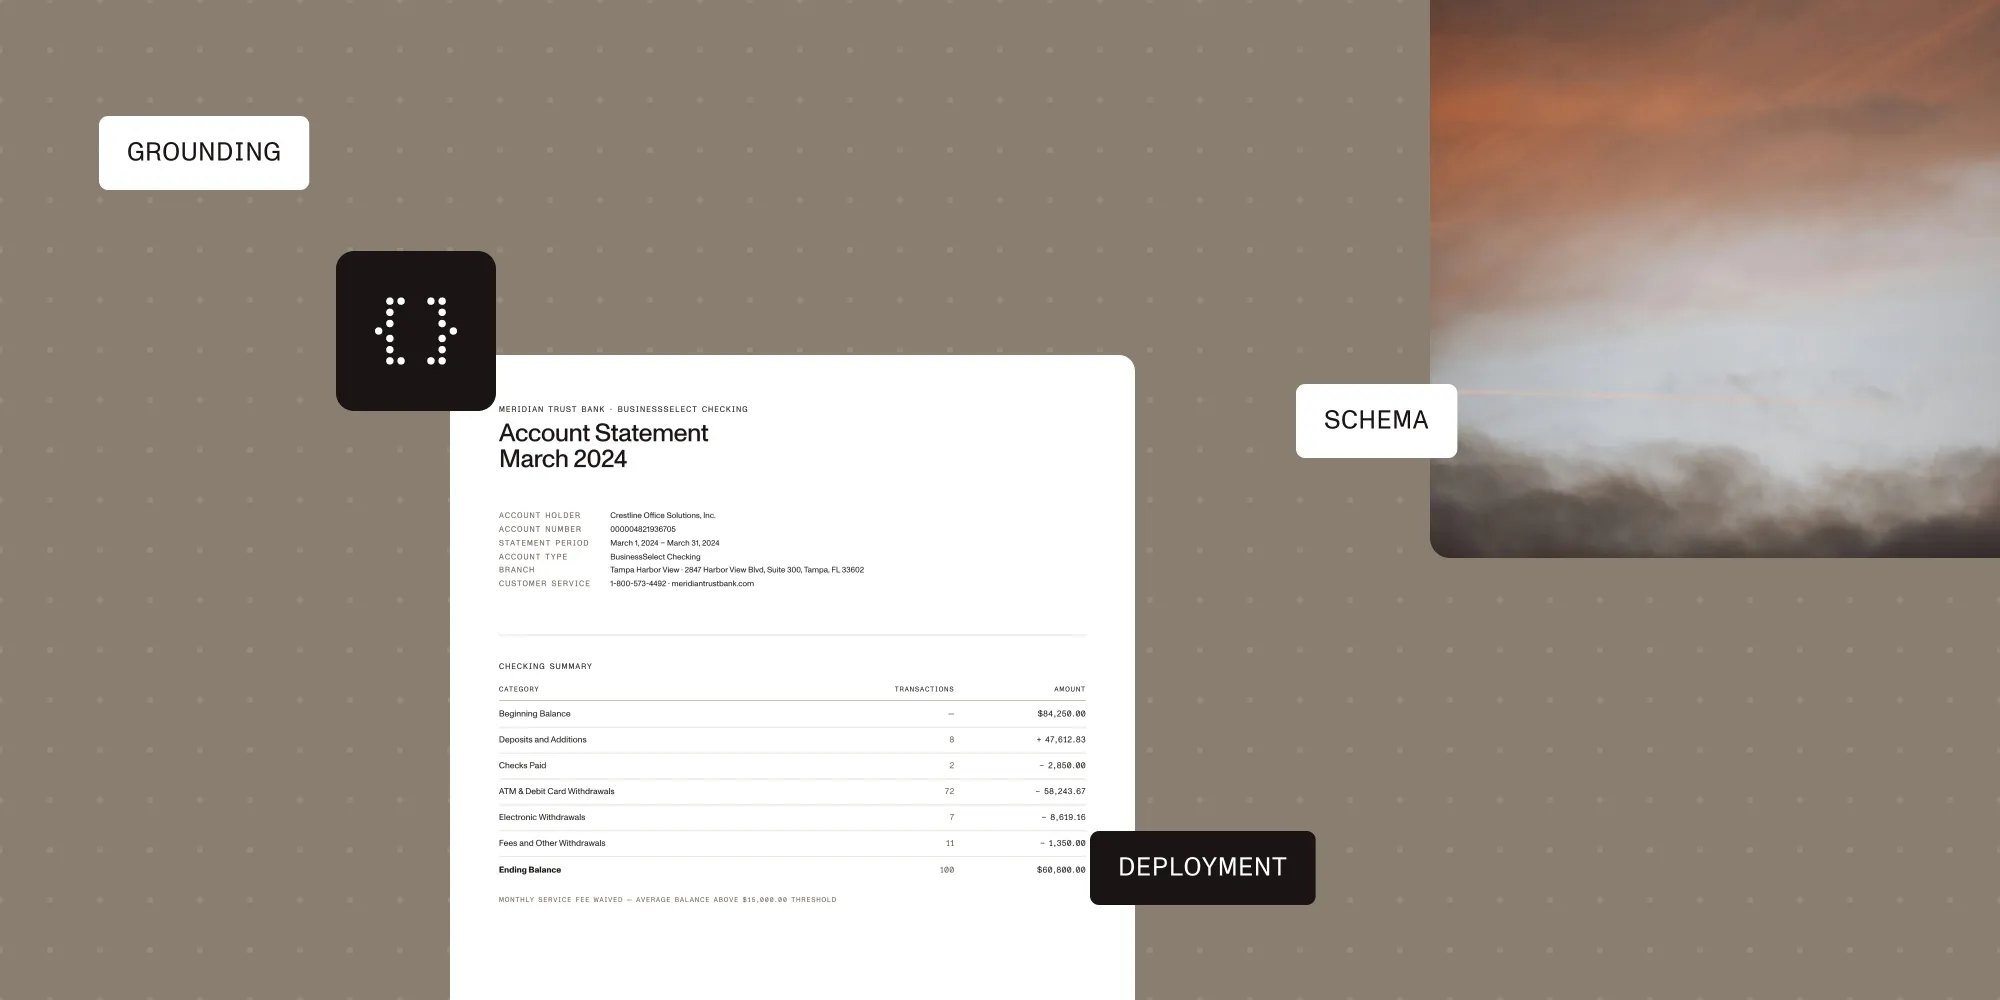
Structured output with per-field confidence scores through the Nutrient Data Extraction API.
- There’s no universal best Landing AI alternative. Choose by how each value is grounded, what a reviewer needs beside it, how much schema control you want, where documents may be processed, and what your page mix costs.
- Choose Nutrient when a bounding box and a grounding match label have to arrive with every extracted value, with a per-field confidence signal when the engine provides one, and when the same platform may also need to view, edit, redact, or sign the document afterward.
- Choose Reducto when agentic parsing of difficult layouts, citations, and private or air-gapped deployment lead the evaluation.
- Choose Extend when a hosted operating layer with saved processors, versions, evaluations, and a built-in review step matters as much as the extraction call.
- Choose LlamaIndex when the retrieval stack is already LlamaIndex and parsing plus schema extraction should stay inside that ecosystem.
- Keep Landing AI on the shortlist when parsing, classification, sectioning, and splitting a multidocument file should come from one parse-first API.
For the wording “best Landing AI alternatives,” Nutrient Data Extraction API is the pick: it maps a document to a JSON Schema you define and returns each value with a bounding box, a page number, and a grounding match label in the same response, plus a confidence signal when the engine provides one, and the wider Nutrient platform covers viewing, editing, redaction, and signing after extraction. What decides the choice is the evidence a reviewer needs, how much of the taxonomy you control, where documents may be processed, and what happens to the file next. Reducto fits teams whose central problem is agentic parsing of difficult layouts with citations and private deployment. Extend fits teams that want a hosted operating layer around the same calls. LlamaIndex fits retrieval stacks already built on LlamaIndex. Unstructured fits connector-driven ingestion into vector stores. Google Document AI and Azure AI Document Intelligence fit teams standardized on those clouds.
Each capability below is described from the vendor’s own documentation.
What Landing AI’s Agentic Document Extraction does well
Landing AI’s document product is Agentic Document Extraction (ADE). Its documentation(opens in a new tab) describes five APIs: Parse converts a document into structured Markdown with hierarchical JSON, Extract pulls specific fields, Classify assigns categories to pages, Section generates a table of contents, and Split separates a multidocument file into sub-documents.
Parse is the entry point, and its chunk model is why teams reach for ADE. Landing AI documents chunks for text, tables, images, form fields, and barcodes, and states that the output “includes page numbers and coordinates for each chunk,” which is what lets an interface highlight an element on the page. The documentation also describes layout-agnostic parsing that works without templates, so a new document type doesn’t start with a labeling project.
Extract(opens in a new tab) works from a schema you supply, and Landing AI documents an unlimited schema size: no stated limit on fields, nesting levels, or characters. Field metadata references the parse chunks behind each value.
Landing AI’s pricing documentation(opens in a new tab) describes credit-based pricing, a free Explore tier whose credits expire, a paid Team tier, and Enterprise plans with custom pricing that add virtual private cloud (VPC) and on-premises deployments.
Why teams look beyond Landing AI
The reasons usually concern the system around extraction, not parsing quality:
- A review queue needs a per-field confidence signal to threshold on, not only a region to open.
- Part of the corpus should run on a path that doesn’t use vision language models (VLMs), so a rerun returns the same data.
- Documents have to stay inside a boundary that only an enterprise deployment covers.
- The application also has to view, annotate, redact, compare, or sign the document afterward.
- Retrieval-augmented generation (RAG) ingestion needs connectors and chunking more than named fields.
None of these are defects in ADE. They’re places where a different product shape carries more of the work.
Criteria that matter in production
Score every candidate against the same requirements before running documents.
1. Grounding a reviewer can open
Ask what arrives beside a value: a page number, a bounding box, source text, or a chunk reference you resolve yourself. Grounding only helps when your interface can highlight the region without a second lookup.
2. Confidence and routing
A score decides which values move automatically, so its scope matters more than its magnitude. Confirm whether it describes optical character recognition (OCR) quality, a whole element, or one field, and don’t assume two vendors’ scores mean the same thing.
3. Schema and taxonomy control
Decide whether you want to write fields in a request or train a processor on labeled examples. Zero-shot schemas and per-request labels make a new document type a text change; trained models trade that for tighter control of a stable document family.
4. Deployment and data boundary
Confirm where files, artifacts, model calls, and logs live for the mode you plan to run. A product can self-host its base pipeline while its deepest mode calls a hosted model, so validate the combination, not the label.
5. Processing depth and price shape
Compare the bill your workflow produces, not the entry rate. Include parsing, extraction, classification, deeper modes, retries, and review time. A credit price and a per-page price aren’t comparable until both run your page mix.
6. What happens after extraction
Decide whether viewing, redaction, comparison, or signatures belong to the same vendor, and whether a second integration is acceptable.
Landing AI alternatives at a glance
“Grounding” here means source locations a reviewer can use to connect a value to the document. It doesn’t mean a score proves the value is correct.
| Platform | Class | Genuine strength | Grounding and output | Deployment | Choose it when |
|---|---|---|---|---|---|
| Nutrient Data Extraction API | Grounded extraction API and platform | Per-field evidence on every value; four modes priced by depth | Spatial JSON or Markdown; bounding boxes, page numbers, match labels, confidence | Hosted API, or your own infrastructure | Fields need review evidence and the work continues afterward |
| Reducto(opens in a new tab) | Agentic parse-and-extract platform | Agentic parsing of difficult layouts with schema extraction | Optional citations: source text, coordinates, confidence | Hosted, VPC, or air-gapped, per its documentation | Difficult documents and private deployment lead the evaluation |
| Extend(opens in a new tab) | Platform with a hosted operating layer | Saved processors, versions, evaluations, a review step | Optional citations and per-field metadata | Managed cloud, bring your own cloud (BYOC), or hybrid | An operations team owns the workflow |
| LlamaIndex(opens in a new tab) | Parse-and-extract in a retrieval framework | Parsing tiers plus schema extraction | Markdown from LlamaParse; schema output with citations from LlamaExtract | Managed cloud; self-hosted and BYOC for enterprise plans | The retrieval stack is already LlamaIndex |
| Unstructured(opens in a new tab) | Ingestion toolkit | Partitioning, chunking, enrichment, connectors | Typed elements and chunks, not named fields | Managed, private, or open source | The destination is a vector store |
| Google Document AI(opens in a new tab) | Hyperscaler service | Processor catalog with a Custom Extractor | Entities with confidence and page anchors | Google Cloud | The workload already runs on Google Cloud |
| Azure AI Document Intelligence(opens in a new tab) | Hyperscaler service | Prebuilt, template, and neural models plus classifiers | Typed field values with confidence | Azure | Azure defines the operating environment |
This isn’t a ranking. An ingestion toolkit solves a different problem from a grounded field-extraction layer.
Seven alternatives to Landing AI
1. Nutrient Data Extraction API
Nutrient Data Extraction API parses PDFs, scans, images, and Office files into spatial JSON or Markdown, and its extract endpoint maps a document to a JSON Schema you define.
The distinction is what arrives with each field. The citations and confidence guide documents per-field metadata that mirrors the extracted data: a bounding box, a page number, the source boxes behind the value, a match label such as id_match, fuzzy_match, or not_found, and a composite confidence score from zero to one. The guide is explicit that the score is a relative signal rather than a probability, and that match is the clearest grounding signal for review logic — routing fuzzy_match and not_found to a person is a rule you can write on day one. The companion post on document extraction confidence scores shows a high-scoring value pulled from the wrong column.
Depth is a per-request decision. Four processing modes run text, structure, understand, and agentic pipelines, priced in the pricing guide at 1, 1.5, 9, and 18 credits per page, with extraction adding a fixed 6 credits per page. Text and structure modes don’t use a VLM, which is the path to choose when a rerun should return the same data. The classify endpoint, POST /extraction/classify, scores a document zero-shot against labels you supply in the request and returns a ranked list of per-label scores at one credit per page.
Choose Nutrient when:
- Per-field confidence and bounding-box grounding are required before a value moves automatically.
- Part of the workload should run on a path that doesn’t use vision language models.
- Processing has to run on your own infrastructure through AI Document Processing or Document Engine.
- The application also needs viewing, editing, redaction, or signatures around the data.
Landing AI’s Section and Split operations have no direct equivalent here: the Data Extraction API documents parse, extract, and classify, so a multidocument packet needs the classification result plus your own page-range logic.
2. Reducto
Reducto(opens in a new tab) is a focused agentic parsing and extraction platform. Its Extract API accepts a schema, and its citations documentation(opens in a new tab) describes returning source text, page coordinates, and confidence with extracted values. Reducto documents software as a service (SaaS), VPC, and air-gapped deployment options(opens in a new tab), and states that large language model (LLM) outputs are inherently nondeterministic — the right assumption to design caching and review rules around.
Choose Reducto when agentic extraction from difficult layouts is the central job and your team will own the review interface. The Reducto alternatives guide covers that lane.
3. Extend
Extend(opens in a new tab) covers parsing, extraction, classification, splitting, editing, and multistep workflows, and pairs the API with Studio for visual configuration. Saved processors carry draft and published versions, tracked runs, and evaluation sets, and a workflow can pause at a review step where a person inspects the document beside the extracted fields. Its deployment guide(opens in a new tab) documents managed cloud, bring your own cloud, and hybrid deployments.
Choose Extend when an operations team, rather than an engineering team, should own the document process end to end. The Extend alternatives guide covers where that layer helps.
4. LlamaIndex
LlamaIndex splits the work between two services. LlamaParse(opens in a new tab) is the managed parser, with processing tiers and word, line, and cell grounding, and LlamaExtract(opens in a new tab) maps a document to a caller-defined schema and can return citations and reasoning with the values. Self-hosted and bring-your-own-cloud deployment are documented for enterprise customers.
Choose LlamaIndex when parsed content flows straight into a LlamaIndex retrieval pipeline. Budget for a second vendor if the application later needs embedded viewing or signing.
5. Unstructured
Unstructured(opens in a new tab) treats documents as data preparation. It partitions files into typed elements, applies chunking, enrichment, and embedding, and moves content from sources to retrieval destinations through its workflow model(opens in a new tab). A managed platform and an open source library cover the hosted and local paths.
Choose Unstructured when the job is turning many repositories and file types into retrieval-ready chunks. Pair it with an extraction API when a reviewer also needs a grounded business field.
6. Google Document AI
Google Document AI(opens in a new tab) organizes capabilities into processors. Custom Extractor handles caller-defined entities and returns confidence with page anchors, Form Parser(opens in a new tab) returns key-value pairs, checkboxes, and tables, and pretrained processors cover common document types.
Choose Google Document AI when the application already runs on Google Cloud and managed processors fit the document mix. The design work becomes processor selection, region, and version pinning.
7. Azure AI Document Intelligence
Azure AI Document Intelligence(opens in a new tab) combines OCR and layout analysis with prebuilt models, custom template and neural models, and document classifiers, and returns strongly typed field values. Microsoft positions Azure Content Understanding(opens in a new tab) as the newer schema-first service across documents, images, audio, and video.
Choose Azure AI Document Intelligence when Azure already defines the operating environment and labeled custom models suit your main document types.
Scenario-based recommendations
The useful answer to “Landing AI vs. other document extraction APIs” is a set of conditions.
- Grounded fields in a review queue — Choose Nutrient when each value must arrive with a bounding box, a match label, and a confidence signal a queue can threshold.
- Difficult layouts and private deployment — Choose Reducto when agentic extraction and an air-gapped option lead the requirements.
- An operations-owned document process — Choose Extend when processors, evaluations, and a review step should ship as product features.
- Retrieval inside LlamaIndex — Choose LlamaIndex when the index, the agents, and the parser stay in one framework.
- Connector-driven ingestion — Choose Unstructured when sources, destinations, and chunking are the larger problem.
- Google Cloud alignment — Choose Google Document AI when managed processors remove more work than a specialist API would.
- Azure alignment — Choose Azure AI Document Intelligence when prebuilt and trainable models fit the document mix.
- A parse-first pipeline with sectioning and splitting — Keep Landing AI when Parse, Section, and Split belong beside field extraction.
Run a fair proof of concept
A comparison page builds the shortlist. Your documents decide the result.
- Collect 30–50 representative files, including poor scans, dense tables, handwriting, and multidocument packets.
- Define one output contract — the same fields, types, and missing-value rules for every candidate.
- Score field values and document structure separately, so strong Markdown doesn’t hide a failing field.
- Open every citation, and count a correct value with unusable grounding as a grounding failure.
- Rerun a sample to measure how much model-based modes vary between runs.
- Test the deployment you would run, including retention, logs, and where model calls go.
- Model total cost on your page mix: parsing, extraction, classification, retries, and review.
The best document parsing APIs guide gives another view of API shape and production fit.
FAQ
Nutrient Data Extraction API is the pick for this wording, because it maps a document to your JSON Schema and returns every value with a bounding box, a page number, and a grounding match label, plus a confidence signal a review queue can route on when the engine provides one. Reducto fits agentic extraction from difficult layouts with citations and private deployment. Extend fits teams that want a hosted operating layer with processors, evaluations, and review. LlamaIndex fits retrieval stacks already built on LlamaIndex, and Unstructured fits connector-driven ingestion. Google Document AI and Azure AI Document Intelligence fit teams standardized on those clouds.
Nutrient returns per-field metadata with a match label, a page number, and bounding boxes for the source regions, plus a composite confidence score from zero to one when the engine provides one, and describes that score as a relative signal rather than a probability. Reducto documents confidence alongside citation source text and page coordinates. Google Document AI returns confidence on extracted entities, and Azure AI Document Intelligence returns confidence on typed fields. Landing AI documents page numbers and coordinates on each chunk. Verify what a score covers on the operation you plan to call.
Nutrient AI Document Processing runs the extraction engine on your own infrastructure through the Data Extraction SDK in Python and Java, and Document Engine self-hosts the surrounding document processing. Reducto documents VPC and air-gapped deployments, Extend documents bring your own cloud and hybrid models, and LlamaIndex documents self-hosted and bring-your-own-cloud options for enterprise customers. Unstructured offers private deployment and an open source library. Landing AI documents VPC and on-premises deployments on Enterprise plans. Validate the exact mode, because a label doesn’t always cover every processing path.
Nutrient returns both and uses both: grounding shows where a value came from, while the confidence score and match label decide whether a person has to look at all. A bounding box alone can’t rank a queue, and a score alone can’t show that a value was read from the wrong column. Treat either signal as a routing input that still needs business-rule validation.
Nutrient charges credits per page by processing mode — 1, 1.5, 9, and 18 credits for text, structure, understand, and agentic — with 6 credits per page added for extraction and 1 credit per page for classification. Landing AI documents a credit model with a free Explore tier whose credits expire, a paid Team tier, and custom Enterprise pricing. Apply each published schedule to the same page mix, and include retries and review time before comparing totals.
Nutrient Data Extraction API documents all three: parse returns Markdown or spatial JSON, extract maps a document to your schema with per-field citations, and classify scores a document zero-shot against labels you supply in the request. It doesn’t document a sectioning or splitting operation, so a multidocument packet needs the classification result plus your own page ranges. Reducto and Extend also cover parsing, extraction, and classification in one product.