DOCUMENT AI MODELS
Models built for documents, measured in public
Explore Nutrient models for verifying claims, detecting form fields, classifying document images, and answering yes/no and multiple-choice questions about documents. Each model links to its public scorecard, demo, leaderboard, and evaluation data where available.
.962
F1 splitting merged PDFs with the document decision model, vs. .825 for the OpenAI Decision API
#1
of 16 systems on the public form-field benchmark (Typed-field F1 @ IoU 0.5)
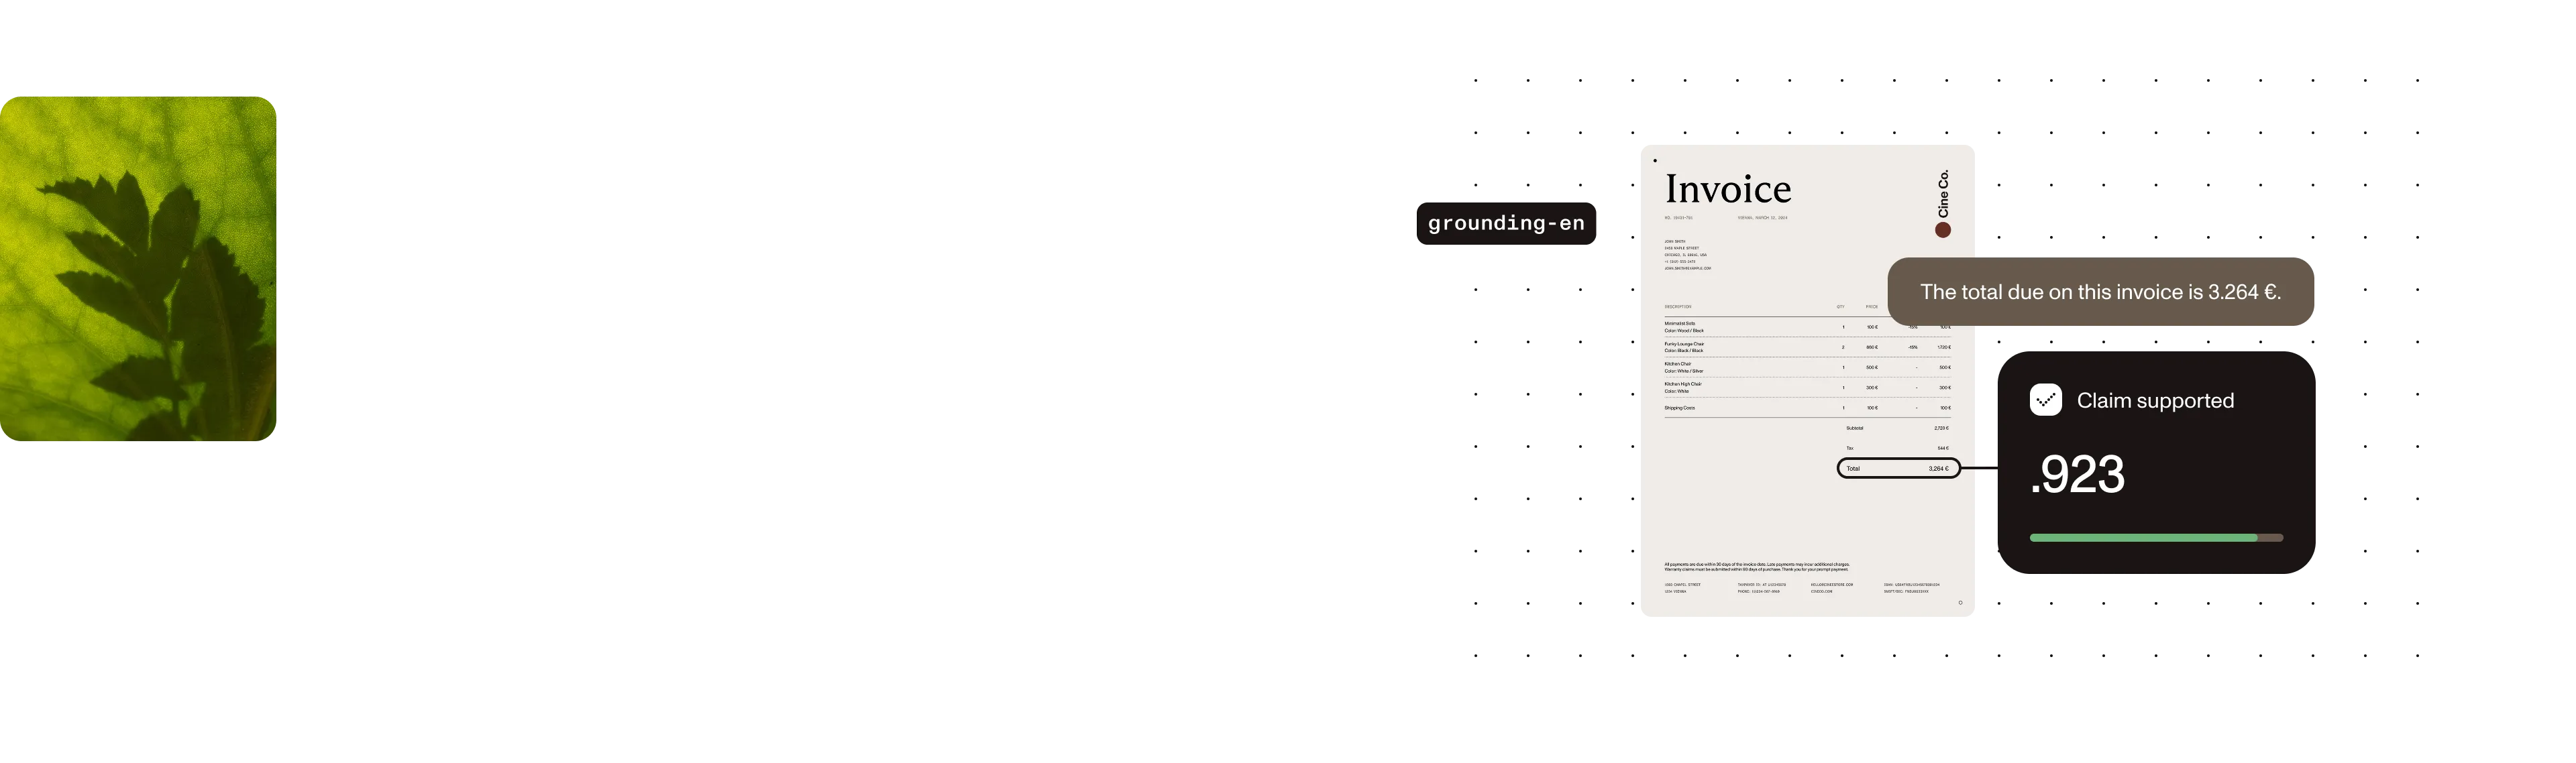
.923
ROC-AUC, number grounding (
grounding-en), vs. .48–.66 for general-purpose NLI baselines5
document models, each with a public model card and leaderboard
WHY SPECIALIZED MODELS
Narrow models, built to be checked
Frontier LLMs are strong generalists, but on precise document tasks, a small model tuned for the job wins — and wins in a way you can verify. Each Nutrient model does one document job well and is shaped to drop into an agent pipeline: ground a claim before a human reviews it, detect every field before a form is filled, label a page before it’s routed. Every Nutrient result on this page is backed by a public dataset, a live demo, and a leaderboard you can rerun.
Grounding and verification
Cross-encoders that score whether document evidence actually supports a claim.
grounding-en grounding-multilingual
.923
ROC-AUC · number-grounding
.48–.66
general NLI baselines
CAVEAT
On general prose, the best listed baseline still edges the multilingual model (.961 vs. .926) — grounding’s edge is numbers, dates, and facts.
Form understanding
Detects every interactive field on a page — bounding box, type, label, radio-group identity — and returns JSON.
form-field-vlm
#1
Nutrient Hybrid · public 16-system leaderboard
#2
Nutrient VLM · public 16-system leaderboard
NOTE
Ranks first and second on the public form-field benchmark — see the full leaderboard below.
Document classification
Open-vocabulary: classifies document and figure images against labels you supply at runtime.
doc-img-classification
.880
broad top-1
.712
specialized top-1
CAVEAT
A listed baseline is slightly higher on synonym robustness.
Document decisions
Answers yes/no and multiple-choice questions about a document, with a confidence score for each answer.
nutrient-document-decision
.962
F1 · splitting merged PDFs (OpenAI Decision API: .825)
.950
F1 · classifying documents (OpenAI Decision API: .896)
NOTE
Answers with a choice and a score. When a workflow also needs a written explanation, pair it with an LLM.
The public form-field leaderboard
Typed-F1 @ IoU 0.5
0.477 #1 OF 16
VLM-only
0.406 #2 OF 16
Box recall
0.790 VS 0.364
Typed-field F1 @ IoU 0.5 — 100 pages, 701 fields
Typed-field F1 @ IoU 0.5 on 100 real pages/701 fields. At a looser IoU 0.2, the best generalist nearly ties on typed-F1 — the specialist’s edge is precise localization (box recall 0.790 vs. 0.364). Full methodology and the live leaderboard on Hugging Face.
Document decisions
One question in, an answer and a confidence score out. Set a threshold: act on confident answers automatically and send the rest to your review queue. The examples below are illustrative.
Fact check
“Is $1,547.00 the total on this invoice?”
Yes
The value is found on the page.
Classification
“Is this an invoice, a contract, or a résumé?”
Invoice
Picked from the three labels given.
Splitting
“Does page 4 start a new document?”
Yes
A new letterhead and layout begin there.
TRY IT
Ask a question about a page
Send the page image and your question to nutrient-document-decision through the AI Gateway decision API. The response gives a probability for the answer, so you decide which answers run automatically.
curl https://api.nutrient.io/ai/v1/systemone \  -H "Authorization: Bearer $NUTRIENT_API_KEY" \  -H "Content-Type: application/json" \  -d '{    "model": "nutrient-document-decision",    "state": {      "page_1": { "type": "image", "source": "data:image/png;base64,..." }    },    "questions": {      "total": {        "type": "noul",        "instructions": "Is $1,547.00 the total on this invoice?"      }    }  }'
# Response: the probability that the answer is yes# { "answers": { "total": { "type": "noul", "noul": 0.98 } },#   "model": "nutrient-document-decision", "usage": { ... } }
Splitting, classification, and fact checking on the public leaderboards
Splitting merged PDFs · F1
0.962 VS 0.825
Classifying documents · F1
0.950 VS 0.896
Fact checking, multilingual · AUC
0.949 VS 0.916
Splitting merged PDFs — F1
Classifying documents, free labels — F1
Fact checking, English — AUC
Fact checking, multilingual — AUC
Splitting and free-label classification are scored with F1, and fact checking (whether a claim is supported by its source document) is scored with AUC. OpenAI’s Decision API and Typesafe AI’s Jev, the two other decision models, were scored on the same tasks. Splitting is compared on our-200, the easiest of the leaderboard’s six splitting sets and the only one where the OpenAI Decision API and Jev have been scored. On long merged streams (OpenPSS-long), nutrient-document-decision scores .959. Every set and the full methodology are on the splitting, classification, and grounding leaderboards.
RUN IT YOURSELF
Open weights, three lines
grounding-en is Apache-2.0 — pull it from Hugging Face. The multilingual, form-field, and classification models are commercial and served through Nutrient DWS Data Extraction. Call the document decision model through Nutrient AI Gateway.
from sentence_transformers import CrossEncoder
model = CrossEncoder("nutrientdocs/grounding-en")score = model.predict([(claim, source_passage)])  # 0–1: is the claim supported?
IN THE PRODUCT
The same models, in your pipeline
Data Extraction API
form-field, grounding, and decision models power structured extraction with per-field confidence and catch extraction mistakes by checking extracted values against the source document.
AI Assistant
grounding verifies generated answers against the source document.
Human-in-the-loop review
low-confidence fields are flagged for a reviewer instead of passed through.
MODEL CATALOG
Open weights where possible, public evidence throughout
The English grounding model is open under Apache-2.0. The multilingual grounding, form-field, image-classification, and document decision weights are commercial, with public model cards and reproducible evaluation benchmarks.
Frequently asked questions
Are the models open source?
grounding-en is Apache-2.0 open weights; multilingual grounding, form-field-vlm, doc-img-classification, and nutrient-document-decision are commercial, with public model cards and reproducible benchmarks.
What is a document decision model?
A model that answers yes/no or multiple-choice questions about a document with a confidence score, instead of writing a paragraph. Set a threshold: act on confident answers automatically and send the rest to your review queue.
What problems does a document decision model solve?
It catches extraction mistakes by checking extracted values against the document. It gives a short answer and a score where a chat model would write a paragraph. And it cuts manual review: You set the threshold, confident answers pass through, and the rest go to your review queue.
How were the benchmarks run?
The benchmarks ran on public datasets with published methodology. Each model links to its dataset and to a live leaderboard Space that you can rerun.
How do I run them?
Run the open-weights models through Hugging Face with transformers or sentence-transformers. Use the commercial models through Nutrient DWS Data Extraction. Call nutrient-document-decision, the document decision model, through Nutrient AI Gateway with a DWS API key.
How do these fit an agent workflow?
They verify and structure before a human step: ground a claim, detect every field, classify a page, or answer a routing question with a score, so an agent hands off checked output.
Which languages does grounding cover?
grounding-en is English; grounding-multilingual covers 15+ languages.
DOCUMENT AI Put benchmarked document models in your pipeline
Talk to Nutrient about document AI, try the same grounding and form field capabilities through DWS Data Extraction, or call Nutrient document decision through AI Gateway.